03
Getting documents in
Turn messy files into clean, labelled, up to date text.
Concept 3.1
Content sources and file formats
Where RAG content comes from, what each file format keeps or loses on the way in, and why the format decides how much work ingestion takes.
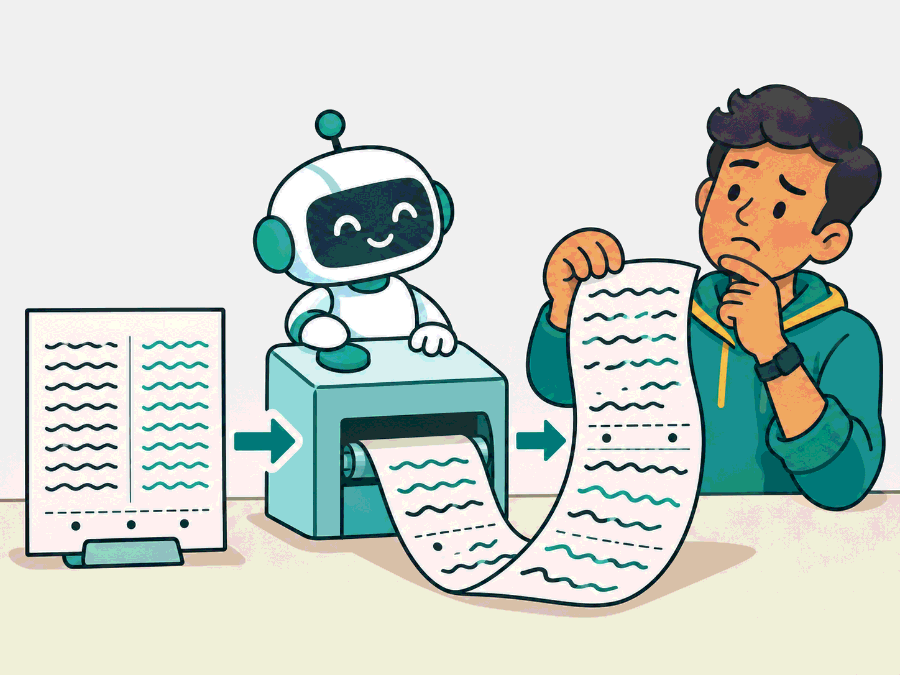
Concept 3.2
Parsing, layout and OCR
How text, reading order and structure are recovered from PDFs and scans, the typical ways parsing goes wrong, and how to check a parser before trusting it.
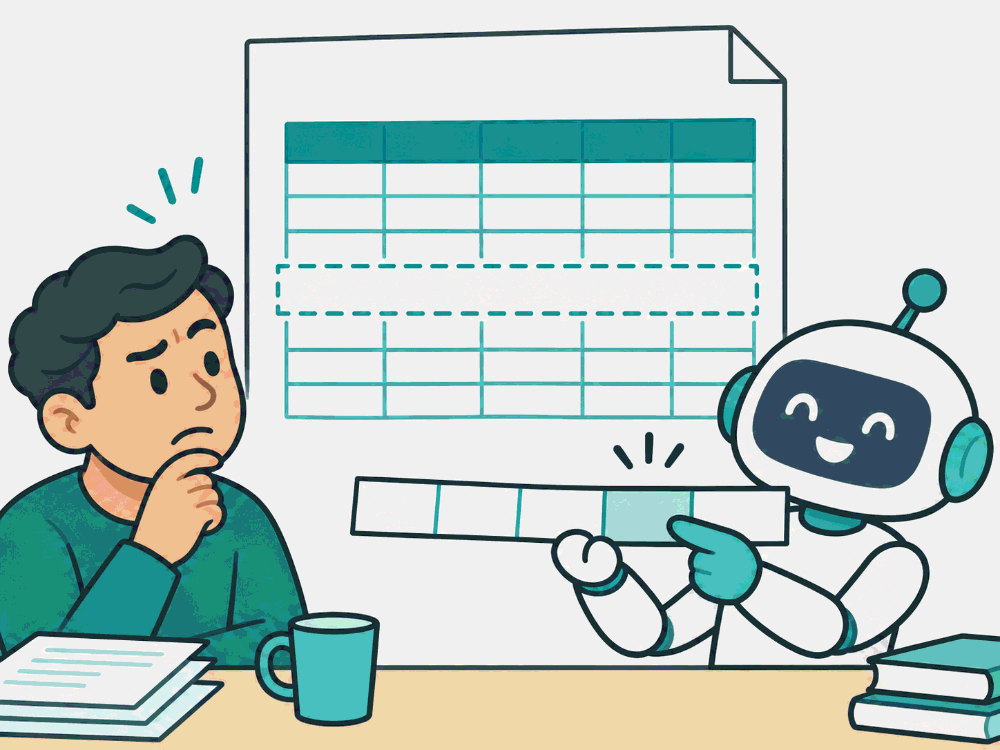
Concept 3.3
Tables, images and mixed content
How to turn tables, charts and images into text that search can find and a model can read correctly, and why tables deserve their own tests.
Concept 3.4
Cleaning, normalization and quality gates
What to clean before indexing, what to leave alone, and the automatic checks that stop broken, duplicate or poisoned documents from reaching search.
Concept 3.5
Metadata, document identity and versioning
How to give every document a stable identity and a version with validity dates, so search returns the version that was true at the right time.
Concept 3.6
Updates, deletes, reindexing and ingestion pipelines
How to keep an index in step with changing documents, when to patch and when to rebuild, and how forgotten deletes leave stale answers behind.
Chapter 3 recap