Chapter 9 · concept 4 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Conflicts, staleness and freshness rules
When two sources disagree, or an old version sits next to the current one, the model needs rules. On our corpus 5 of 8 version questions had an outdated version in the top 3.
A real question
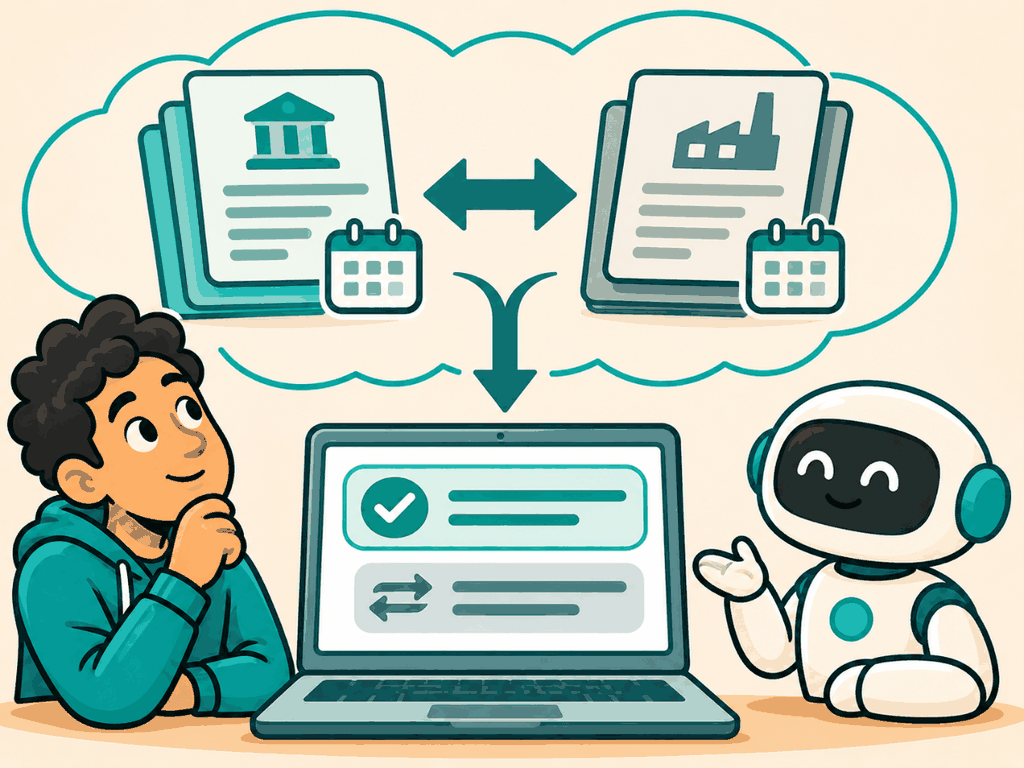
One document says 10 working days, another says 30 days. Which should the answer use?
Neither by luck. You decide the rules: valid version only, more authoritative source first, and when a conflict matters, say so in the answer. The model follows rules; it cannot invent them.
The problem
Why this matters
The model will work out which source is right.
Old and new versions read alike, so both get retrieved. For 5 of our 8 version questions, another version of the same document was in the top 3. Without dates or rules, the model guesses.
Why not the simpler way
Real document collections contain old price lists, superseded policies, handbooks that simplify the official terms, and notices that override both for a while. Retrieval finds all of them, because they talk about the same thing. An answer built from the wrong one is wrong with a valid citation.
The idea
The idea in plain words
Three kinds of disagreement: versions of one document over time (staleness), different documents that say different things (conflict), and temporary overrides such as an endorsement that suspends cover for a period. Each needs metadata and a rule.
A train timetable from last year is still a well-written timetable. It is just not valid today.
How it works
Step by step
 1
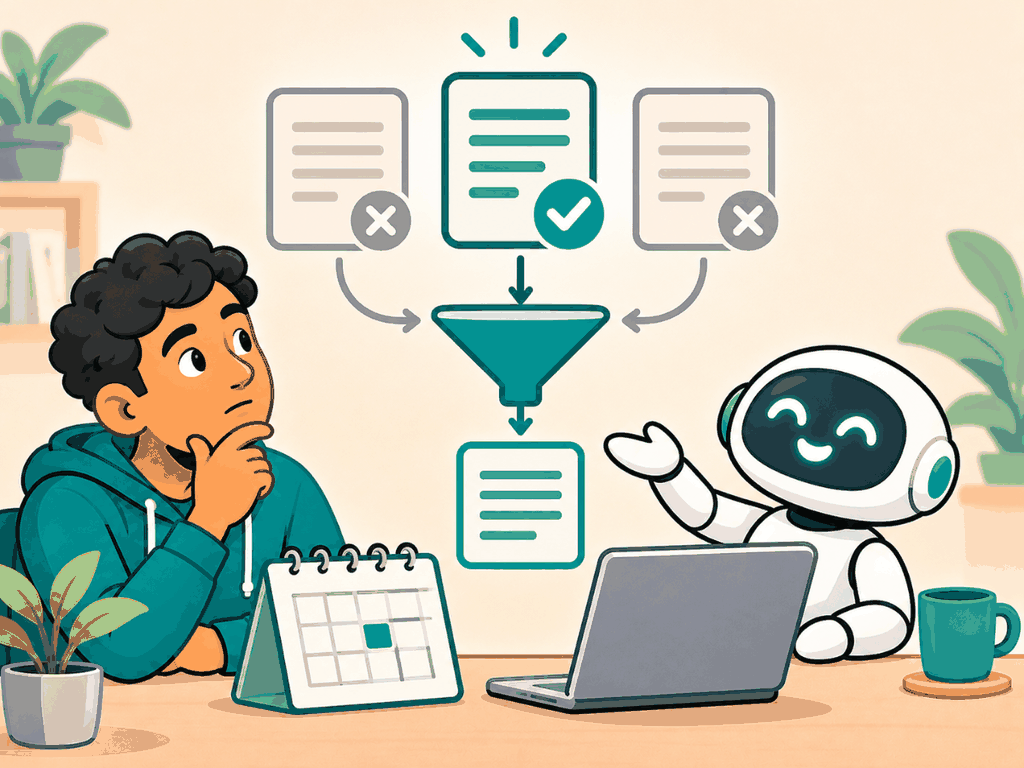
Filter by validity
Store effective_from and effective_to on every chunk. Keep only versions valid on the date in question: today, or the date the user asks about.
 2
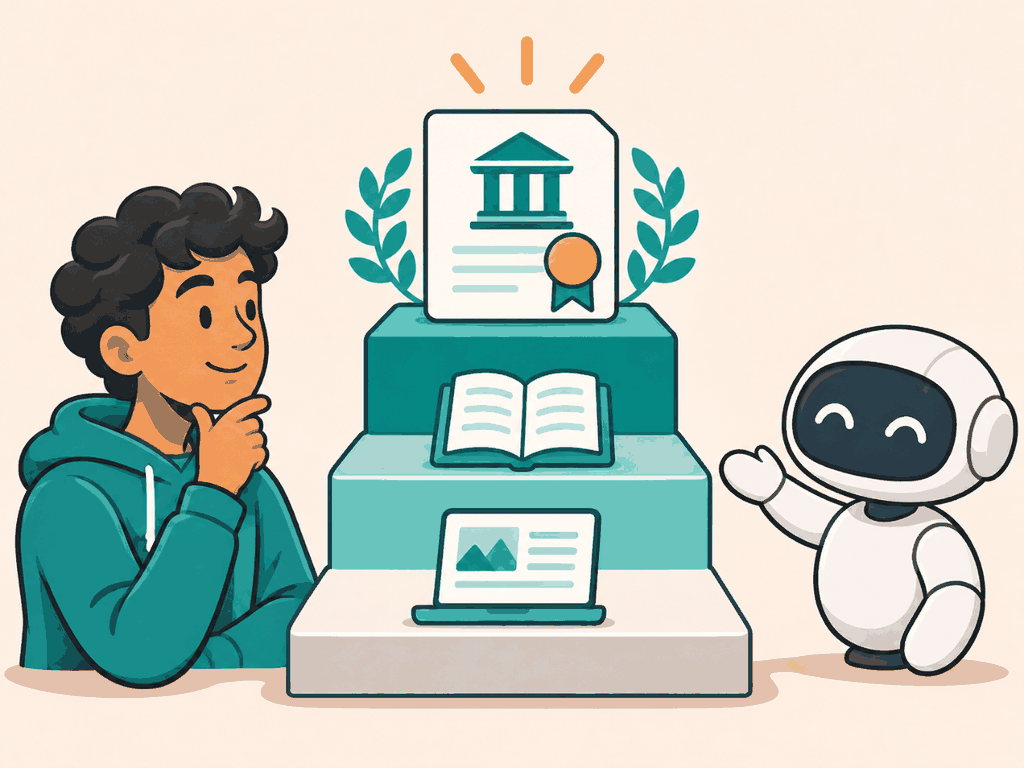
Rank sources by authority
Policy conditions over a handbook, an endorsement over the base policy, an official notice over a blog post. Write the order down.
 3
Show conflicts that matter
Pass version and source type to the model. When sources disagree, answer by the rule and mention the other value.
In detail
Validity. Every chunk carries effective_from and effective_to (RAG-11). A question about "today" uses today; a question about "September 2025" uses that date.
Authority. A small table maps source types to a rank. Pass the source type into each chunk's label so the model can apply the rule, and apply it in code where you can.
Overrides. Endorsements and notices are valid for a period and override the base text in that period. Our flood questions depend on postcode and date for exactly this reason (RAG-30).
Freshness rules. Some answers should expire: an outage status from yesterday is stale today. Store a time-to-live per source type.
The code
Try it in Python
AUTHORITY = {"policy-conditions": 3, "endorsement": 3, "tariff-sheet": 3, "product-sheet": 2, "handbook": 1}

def label(chunk) -> str:
    m = chunk.meta
    return f"({m['title']}, version {m['version']}, valid {m['effective_from']} to {m['effective_to'] or 'now'}, source type {m['type']})"

RULE = """If sources disagree, use the one with the higher source type in this order:
policy conditions and endorsements, then product sheets, then handbooks.
Say which value you used and mention the other."""
See it
What we measured
Measured · outdated versions in the top 3
Polder corpus, 34 recursive 512 token chunks, hybrid search. Version questions: 8 golden questions over the tariff sheets (3 versions) and the outsourcing policy (2 versions).
Measured 2026-11-04 with corpus/scripts/measure-parts-6-7.mts; filter numbers measured 2026-11-03 on vector search. Model behaviour with the authority rule was not measured (not measured yet).
Try it on a real example
“How long does Polder Verzekeringen take to decide on a complete claim?”
Two retrieved sources
Policy conditions: “Polder Verzekeringen decides on a complete claim within 30 days.”
Both are retrieved. A model may pick either, or average them into something neither says.
Choosing
Use it when, avoid it when
- Validity dates and source types on every chunk
- A written authority order, applied in code and in the prompt
- Leaving old versions searchable without end dates
- Letting the model decide authority on its own
What it costs · Metadata at ingestion and a short rule in the prompt.
In production
Add conflict and version questions to the golden set; ours has 2 conflict and 8 version questions. Alert when two valid documents of the same authority disagree; that is a content issue to fix at the source. When documents are updated, end-date the old version's chunks in the same job that adds the new ones (RAG-12).
Watch out
Common mistakes
- The newest document always wins. A handbook can be newer and still rank below the conditions.
- Conflicts are rare. 5 of 8 version questions had an old version in the top 3.
- Hiding conflicts is cleaner. When a user may have read the other value, say why it does not apply.
Check yourself
Remember this
Remember these
- Old and new versions are retrieved together: 5 of 8 version questions here.
- Filter by validity dates before ranking (RAG-11, RAG-29).
- Write down which sources outrank which.
- When sources conflict, answer by the rule and name the other value.
Say it in an interview
- 01Old and new versions are retrieved together; on my corpus 5 of 8 version questions had both.
- 02I filter by validity dates first; that lifted the right version first from 2 to 4 of 5.
- 03A written authority order decides conflicts, not the model.
- 04When sources disagree, the answer follows the rule and names the other value.
- 05Conflict and version questions are part of my golden set.
Quick quiz