Chapter 8 · concept 1 of 1 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Retrieval failure analysis playbook
A fixed order of checks for any wrong answer, from "is it in the corpus" to "did the model use it", applied to the three questions vector search missed on our corpus. Each check names its fix.
A real question
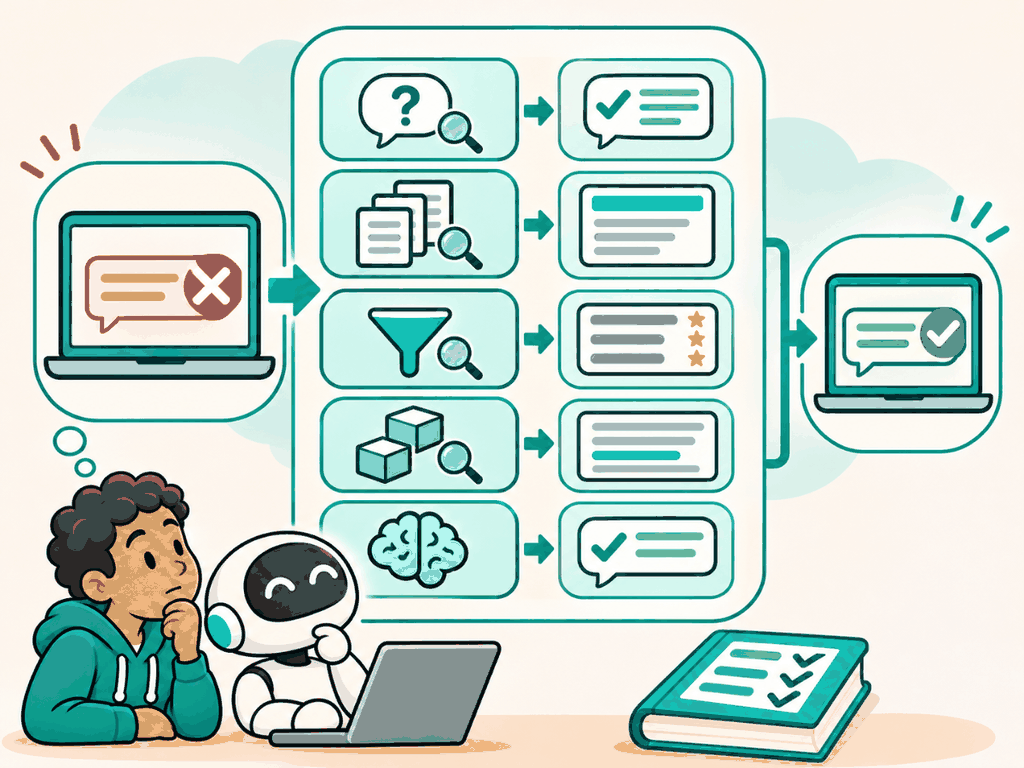
The system gave a wrong answer. Where do you start?
Not by changing things. Ask five questions in order: is the answer in the corpus, is it whole in one chunk, did filters allow it, what rank did each retriever give it, and did the model use it? The first “no” names the fix.
The problem
Why this matters
When answers are wrong, try a new model, a new prompt or bigger chunks until it gets better.
On our corpus, all three vector-search misses were the same kind: the right chunk existed, whole, at rank 4 to 6. Hybrid search fixed all three. Bigger chunks or a new prompt would have fixed none.
Why not the simpler way
RAG has many moving parts, and every part can be blamed. Without a method, teams change the embedding model, the chunk size and the prompt at the same time, see a different number, and cannot tell why. RAG-18 gave the chunking half of this playbook; this page adds retrieval and generation.
The idea
The idea in plain words
Treat the pipeline as a chain and test each link in order, with the golden answer as the probe. The first link that fails is the cause; later links cannot be judged until it is fixed.
A plumber with no water at the tap checks the main valve, then the pipe, then the tap, in that order. Replacing the tap first is a guess.
How it works
Step by step
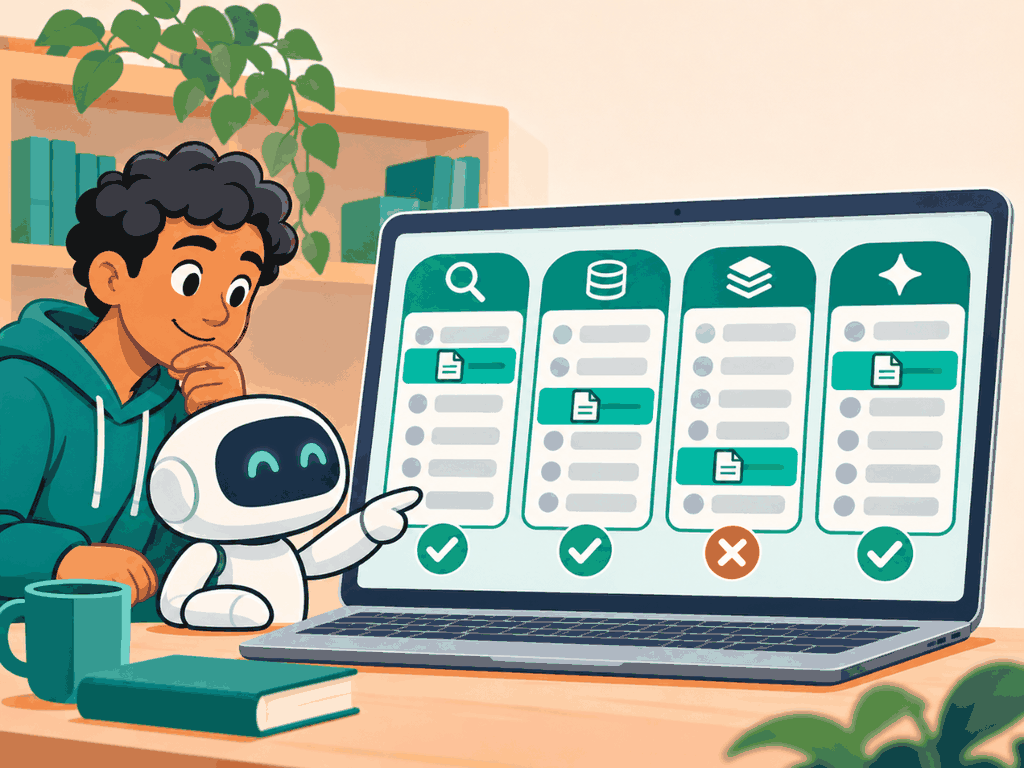
 1
Corpus, chunk, filters
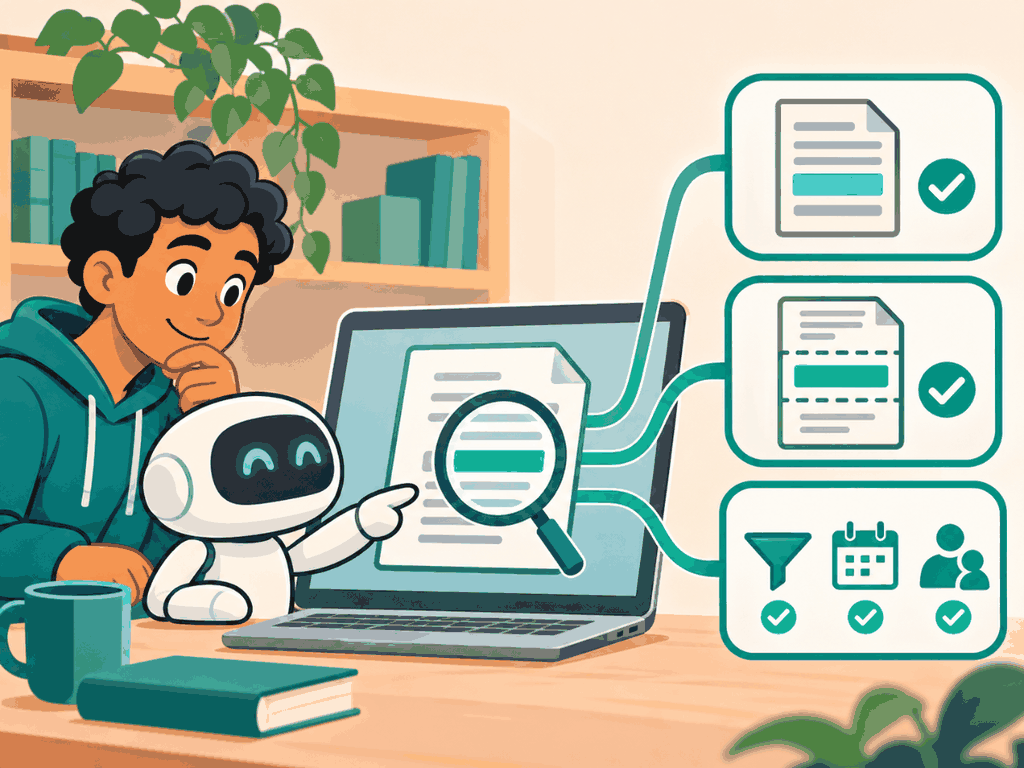
Search the raw text for the answer. Check one chunk holds it whole. Check no filter removed it for this user or date.
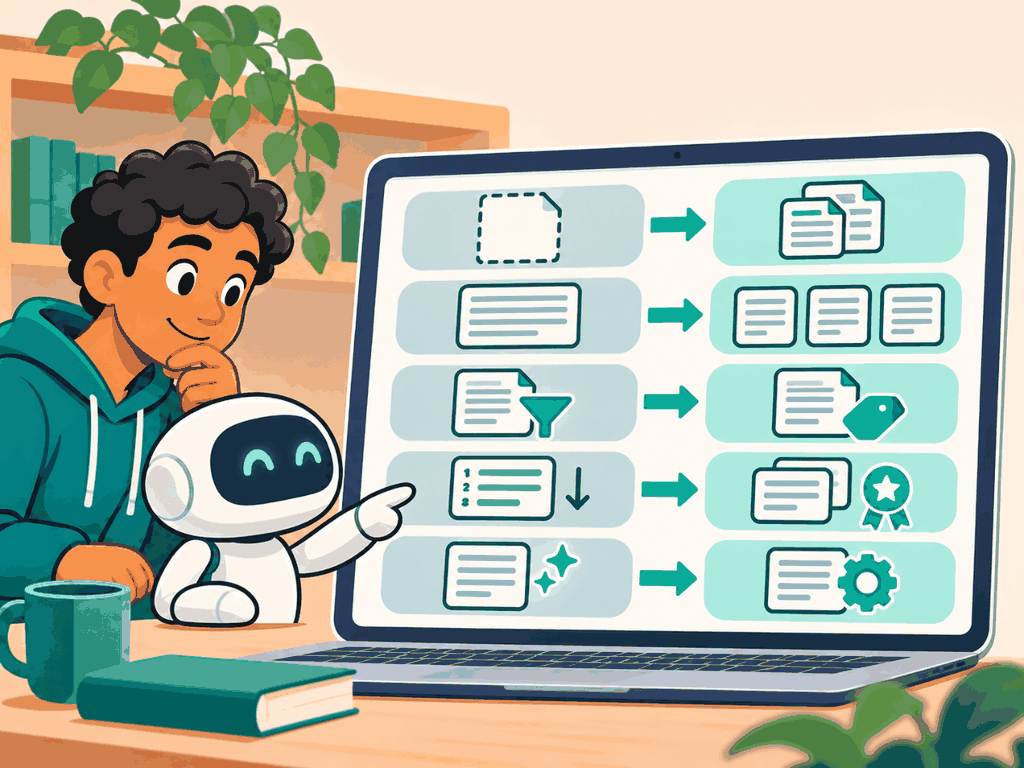
 2
Rank in each retriever
Look up the answer chunk's rank in BM25, vector, fused and reranked lists. The list that loses it is the one to fix.
 3
The step names the fix
Missing: ingestion. Split: chunking. Filtered: metadata. Ranked low: hybrid or reranking. In the prompt but ignored: generation.
In detail
1. In the corpus? Search the raw, parsed text for the answer string. No: ingestion or a missing document (Part 2).
2. Whole in one chunk? No: the boundary split it; fix size, overlap or strategy (RAG-15, RAG-18).
3. Allowed by filters? No: wrong metadata, wrong version date or an access role problem (RAG-11, RAG-29).
4. Rank per retriever. Found but low: hybrid search (RAG-28) or reranking (RAG-31). Not in any top 50: the wording of question and chunk differ; look at query rewriting (RAG-26) or the embedding model (RAG-21).
5. Used by the model? In the prompt but the answer is wrong: generation (Part 6), such as lost in the middle (RAG-35) or a weak grounding prompt (RAG-34).
The code
Try it in Python
def diagnose(g, corpus_text, chunks, ranks, prompt_ids=None):
    ev = g["evidence"]
    if ev not in corpus_text:                    return "missing: fix ingestion"
    holders = [c.id for c in chunks if ev in c.text]
    if not holders:                              return "split: fix chunking"
    if not any(ranks["allowed"].get(h) for h in holders):
        return "filtered: check metadata and access"
    best = {name: min(r.get(h, 999) for h in holders) for name, r in ranks.items() if name != "allowed"}
    if min(best.values()) > 50:                  return f"not found {best}: check wording, model"
    if best.get("final", 999) > 3:               return f"ranked low {best}: hybrid or rerank"
    if prompt_ids is not None and not set(holders) & set(prompt_ids):
        return "dropped before the prompt: check k and packing"
    return "retrieval ok: look at generation"
See it
What we measured
Measured · vector misses and where they were fixed
Polder corpus, 34 recursive 512 token chunks, 47 golden questions. Misses are questions whose answer chunk was not in the vector top 3.
Measured 2026-11-04 with corpus/scripts/measure-parts-4-7.mts. Step 5, whether the model used the chunk, needs model calls and was not measured here.
Try it on a real example
The three questions vector search missed (answer not in its top 3)
“Is there an excess for storm damage?”
Ranked low by vectors only. Rare word “excess”: BM25 finds it, fusion keeps it, the reranker puts it first.
Choosing
Use it when, avoid it when
- The five checks, in order, for every miss
- Per-retriever ranks logged for every golden question
- Changing several parts at once
- Judging a fix by the total only
What it costs · A few lines of logging and a script. The time saved is in not changing the wrong thing.
In production
Build the playbook into your tooling: for every golden question, store the answer's rank in each retriever and whether it reached the prompt. A regression report then reads "3 questions dropped out of the top 3, all in vector search, all insurance", which points at a cause. For live traffic, sample bad answers from user feedback and run the same five checks.
Watch out
Common mistakes
- Wrong answers mean a bad model. Our three misses were all ranking problems.
- Bigger chunks fix misses. Only splits are fixed by chunking; none of ours were splits.
- A fix that raises the total is safe. Check per question for new misses.
Check yourself
Remember this
Remember these
- Check in order: corpus, chunk, filters, ranks, use.
- Log ranks from every retriever per question so the checks take seconds.
- All 3 vector misses on our corpus were ranking problems.
- Re-run the golden set after the fix and compare per question, not just the total.
Say it in an interview
- 01I diagnose misses in order: corpus, chunk, filters, rank per retriever, used by the model.
- 02On my corpus all three vector misses were the right chunk at rank 4 to 6.
- 03Hybrid search fixed all three, and reranking put two of them first.
- 04I log every retriever's rank per golden question, so a regression points to its cause.
- 05I compare runs per question, not just by the total.
Quick quiz