Chapter 7 · concept 6 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Reranking: two stage, cross encoder and LLM rerankers
A fast search finds 10 candidates, then a cross-encoder reads each one with the question and reorders them. On our corpus, answers ranked first rose from 30 to 40 of 47, at about 1.5 seconds per question on a CPU.
A real question
The answer is in the top 10, but at rank 4. How do we get it to rank 1?
Add a second, slower, more careful step. A reranker reads the question together with each of the 10 candidates and scores them again. Only the best few go to the model.
The problem
Why this matters
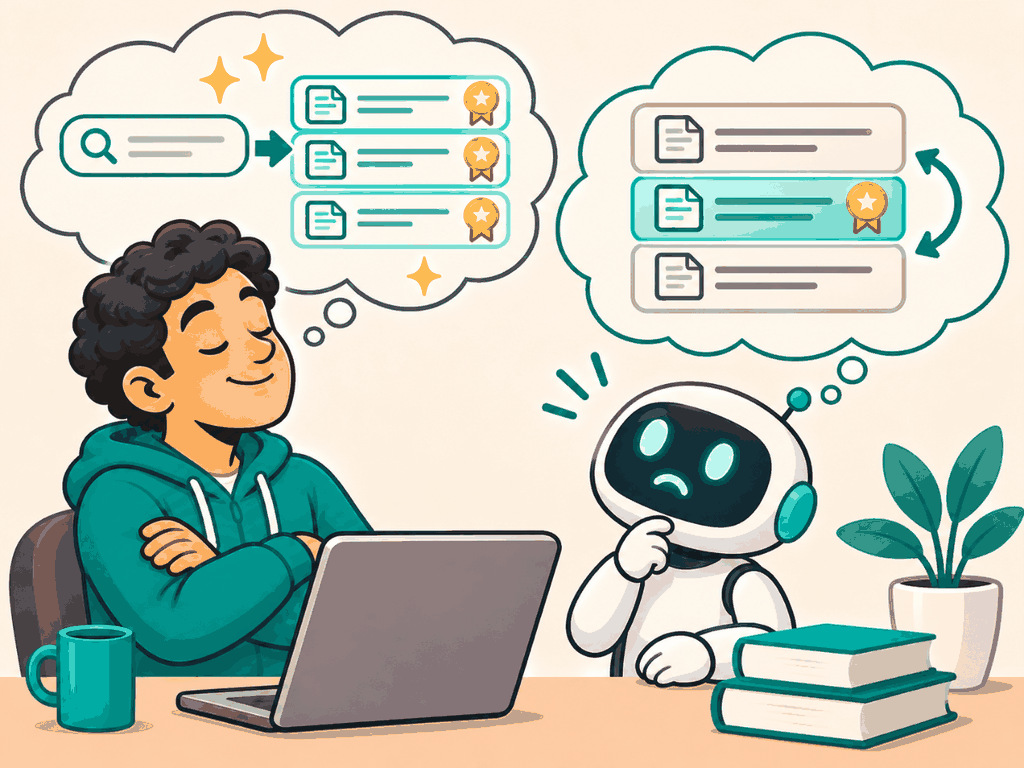
The first search already puts the candidates in the right order.
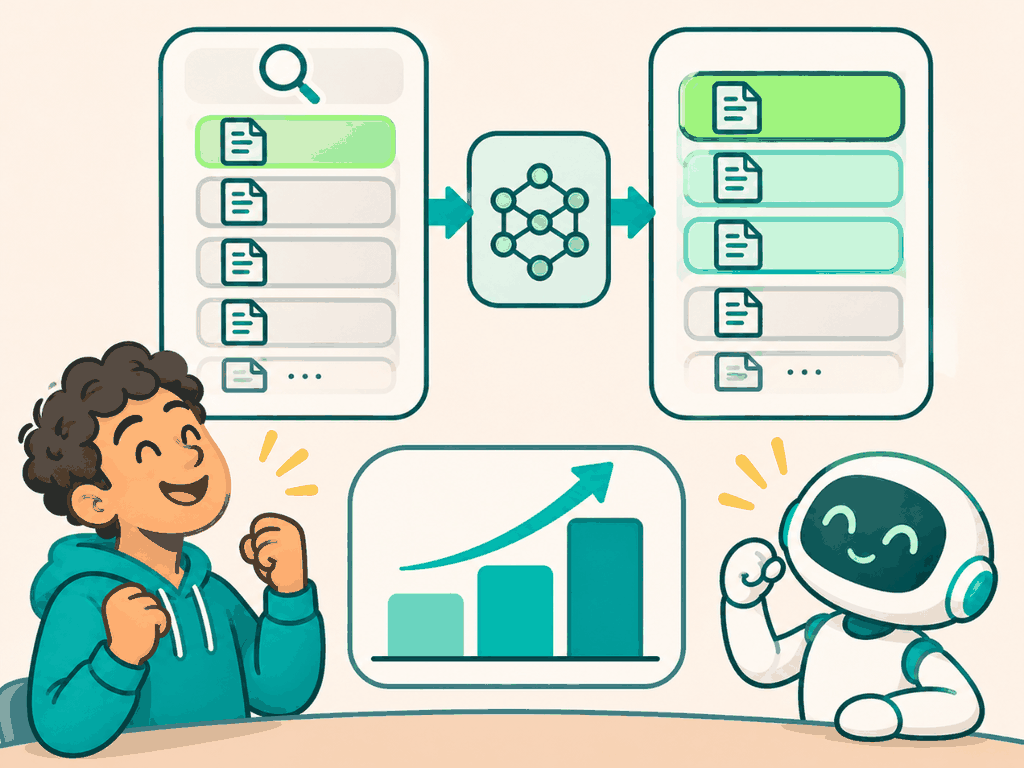
Vector search put the answer first for 30 of 47 questions. After a cross-encoder reranked its top 10, it was first for 40, and in the top 3 for all 47.
Why not the simpler way
Embedding models encode the question and each chunk separately, then compare two summaries. That is what makes them fast enough to search everything, and also why they misjudge close calls: "notice for a price change" looks like any text about notices and terms. When the answer is in the top 10 but not the top 3, the fix is better ordering, not better search.
The idea
The idea in plain words
A bi-encoder (the embedding model) encodes question and chunk apart. A cross-encoder encodes them as one input, so every question word can attend to every chunk word. It is more accurate and much slower, so it only reads the short list. An LLM reranker asks a general model to score or order the candidates; it is flexible and the most expensive.
A recruiter screens 200 CVs in minutes by keywords. The hiring manager then reads the top 10 carefully.
How it works
Step by step
 1
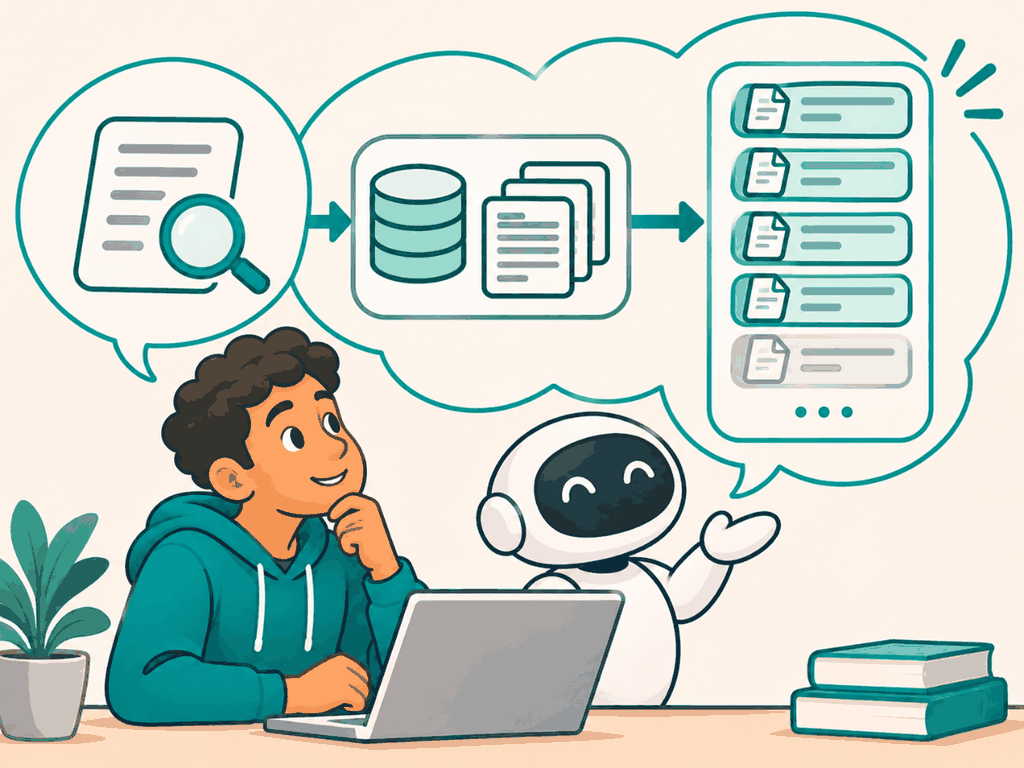
Cheap search finds candidates
BM25, vectors or both return the top 10 to 50. Fast over the whole corpus, rough in its order.
 2
Read each pair closely
A cross-encoder takes “question + chunk” as one input and outputs a relevance score. It sees how the words relate.
 3
Pay in latency
One model pass per candidate. On a laptop CPU, 10 candidates took about 1.5 seconds. Keep the candidate list short, or use a GPU or an API.
In detail
Pipeline. Retrieve N (10 to 50) with hybrid search, rerank, keep the top k (3 to 5) for the prompt (RAG-29).
Models. Open cross-encoders (bge-reranker, ms-marco MiniLM), hosted rerank APIs, or an LLM prompted to rank. We used bge-reranker-base, quantized, in Node on a CPU.
N matters. The reranker cannot fix what the retriever missed; it only reorders. Larger N raises the ceiling and the latency, linearly.
Scores. Reranker scores are not cosine scores. If you use them as a cut-off for "no good match", calibrate on your golden set (RAG-23).
The code
Try it in Python
from sentence_transformers import CrossEncoder

reranker = CrossEncoder("BAAI/bge-reranker-base")

def rerank(question: str, candidates: list[str], keep: int = 3) -> list[str]:
    scores = reranker.predict([(question, c) for c in candidates])   # one pass per pair
    order = sorted(range(len(candidates)), key=lambda i: -scores[i])
    return [candidates[i] for i in order[:keep]]

top10 = hybrid_search(question, k=10)
context = rerank(question, top10, keep=3)
See it
What we measured
Measured · answers at rank 1 and in the top 3, before and after reranking the top 10
Polder corpus, 34 recursive 512 token chunks, 47 golden questions. Reranker: Xenova/bge-reranker-base, q8, transformers.js on a laptop CPU, question + chunk text truncated to the 512 token limit. 14 of the question and answer-chunk pairs were over the limit, but in every one the evidence fell before the cut (corpus/scripts/check-truncation.mts).
Measured 2026-11-04 with corpus/scripts/measure-parts-4-7.mts. One question (g-34) moved from rank 1 to 2 after reranking either list; on the vector list g-08 (“When is a slow connection a line problem rather than Wi-Fi?”) also fell from 1 to 3. LLM rerankers were not measured.
Try it on a real example
“How much notice is given for a price change during a fixed term?”, vector top 10
The vector saw “notice” and “term” and found insurance and banking text first.
Choosing
Use it when, avoid it when
- A cross-encoder over the top 10 to 50 when the answer is found but ranked low
- Reranker scores, calibrated, for no-good-match decisions
- Reranking hundreds of candidates per question
- Expecting a reranker to recover answers the retriever missed
What it costs · One model pass per candidate: about 1.5 s for 10 on a laptop CPU, much less on a GPU. Hosted rerankers charge per search.
In production
Reranking is the largest added latency in retrieval (1.4 s for 10 pairs on CPU in Part 8). Its gain depends on the corpus, so measure it. Batch the pairs, run on a GPU or use a hosted reranker, and cap N. Measure the gain per slice: on our fused results, top-3 recall was already 47 of 47, so reranking only moved answers up within the top 3 (rank 1 from 33 to 40). One question got worse: “Is the fibre outage in postcode 3511 fixed?” went from rank 1 to 2. Check those regressions, not just the average.
Watch out
Common mistakes
- Reranking improves recall. It only reorders; recall at N is fixed by the retriever.
- A reranker never hurts. One of our questions dropped from rank 1 to 2.
- LLM reranking is always best. It is the slowest and most expensive; measure it against a cross-encoder first.
Check yourself
Remember this
Remember these
- Two stages: a fast retriever for recall, a reranker for order.
- A cross-encoder reads question and chunk together.
- On our corpus: answers first rose from 30 to 40 of 47.
- Cost: about 1.5 s per question for 10 candidates on a CPU.
Say it in an interview
- 01I use two stages: hybrid search for the top 10, a cross-encoder to reorder.
- 02A cross-encoder reads question and chunk together, so it judges close calls better.
- 03On my corpus reranking raised answers at rank 1 from 30 to 40 of 47.
- 04It took about 1.5 seconds per question for 10 candidates on a CPU, so I cap N.
- 05I check per-question regressions: one answer moved from rank 1 to 2.
Quick quiz