Chapter 7 · concept 1 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Query understanding, rewriting and expansion
Users type short, vague or follow-up questions. Rewriting can fix that, or break it. We searched 12 questions in full and as short keywords; the same change helped one question and buried another.
A real question
A user types “laptop theft max”. Should the system rewrite it before searching?
Sometimes. Rewriting turns vague or follow-up questions into searchable ones. It can also drop the very words that found the answer. Measure each rewrite on your golden set.
The problem
Why this matters
Rewriting or expanding the question always improves retrieval.
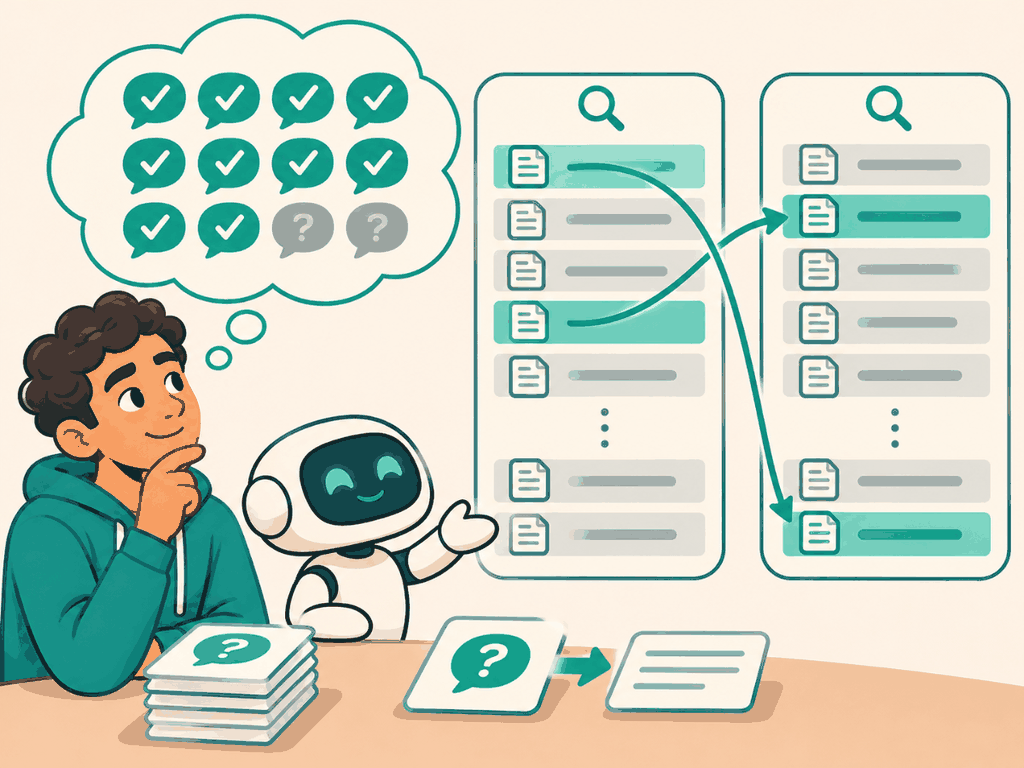
We wrote short keyword forms of 12 golden questions. Vector search found 10 of 12 either way, but individual ranks moved both ways: one answer went from rank 4 to 2, another from rank 1 to 13.
Why not the simpler way
Real questions are not like golden-set questions. They are short ("dividend"), vague ("is it covered?"), full of typos, or depend on the conversation ("and in 2024?"). Search runs on the literal text, so a vague question gets vague results. Query understanding fixes the question before retrieval.
The idea
The idea in plain words
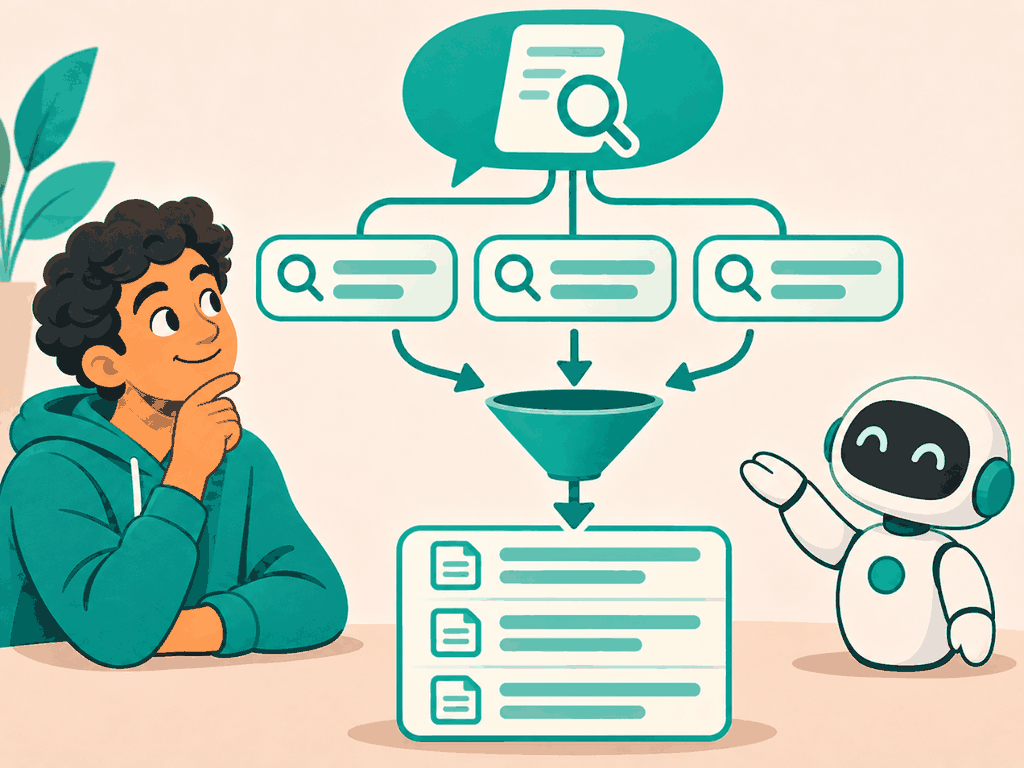
Rewriting turns the user's text into a better search query, usually with a small model. Expansion adds alternatives: synonyms, several phrasings (multi-query), or a hypothetical answer to search with (HyDE, Gao et al., arXiv 2212.10496). Decomposition splits a question with two parts into two searches.
A librarian who hears "that book about the war, the red one" asks a few questions before going to the shelves.
How it works
Step by step
 1
Resolve the conversation
In a chat, rewrite follow-ups into stand-alone questions: “What does the second plan cost?” instead of “and that one?”.
 2
Or search several phrasings
Multi-query: generate a few versions, search each and fuse the results. HyDE: search with a drafted answer instead of the question.
 3
Keep it only if it helps
Run the golden set with and without the rewrite. Keep exact codes, numbers and dates unchanged in every version.
In detail
Conversational rewrite. Give a model the last few turns and the new message; ask for one stand-alone question. Log both the original and the rewrite: when follow-ups fail, the rewrite is the first thing to check.
Multi-query. Ask for 3 phrasings, search each, fuse with RRF (RAG-28). On our 12 questions, fusing the full and short vector results found the same 10 as the full question alone: no gain, and an extra search.
HyDE. Ask a model to write a plausible answer, embed it, and search with that. Answers look more like documents than questions do. The risk is a made-up detail that pulls in the wrong chunk.
Guard exact terms. Extract codes, amounts and dates with a regex before rewriting and check they survive.
The code
Try it in Python
import re

REWRITE = """Rewrite the last user message as one stand-alone search question.
Keep every code, number and date exactly as written. Output only the question.

Conversation:
{history}
Last message: {message}"""

def guard(original: str, rewritten: str) -> str:
    exact = re.findall(r"[A-Z]{1,4}-?\d[\w.-]*|\d+(?:[.,]\d+)?", original)
    return rewritten if all(e in rewritten for e in exact) else original
See it
What we measured
Measured · answer chunk in the top 3, 12 golden questions
Polder corpus, 34 recursive 512 token chunks. Short keyword forms written by us for 12 golden questions. Vector: bge-small. Multi-query: RRF of the full and short vector lists.
Measured 2026-11-04 with corpus/scripts/measure-parts-4-7.mts. No model-written rewrites were tested; those need a model call per question (not measured yet: needs an API key).
Try it on a real example
Full question against a short keyword form, vector search, rank of the answer chunk
g-19
Short: “report damage days” → rank 2
The answer sits in the general conditions: “A claim must be reported within 14 days…”. The short form keeps just those words, and the answer moved up two places.
Choosing
Use it when, avoid it when
- Rewriting follow-ups into stand-alone questions in chat
- Multi-query or HyDE where the golden set shows a gain
- Rewriting questions that contain exact codes without a guard
- Adding expansion because a tutorial did
What it costs · One small model call per question, plus one extra search per added phrasing.
In production
Every rewrite adds a model call before search, usually a few hundred milliseconds and a small cost per question. Route: rewrite follow-ups in chat, leave stand-alone questions with exact codes alone. Track per-slice results; short keyword questions and follow-ups behave differently from full questions.
Watch out
Common mistakes
- Shorter, cleaner queries search better. “laptop theft max” fell from rank 1 to 13.
- Rewriting is only for typos. Its biggest job is follow-up questions.
- Multi-query always raises recall. It added nothing on our 12 questions.
Check yourself
Remember this
Remember these
- In chat, rewriting follow-ups into stand-alone questions is the clear win.
- Multi-query and HyDE add model calls; test them before keeping them.
- Never let a rewrite change codes, numbers or dates.
- On our 12 test questions, short forms kept the total but moved ranks both ways.
Say it in an interview
- 01I rewrite follow-up questions into stand-alone ones; that is the clear win in chat.
- 02I treat multi-query and HyDE as experiments, kept only if the golden set improves.
- 03On my corpus a short keyword form moved one answer from rank 4 to 2 and another from 1 to 13.
- 04A guard checks that codes, numbers and dates survive the rewrite.
- 05I log the original and rewritten query so follow-up failures are easy to trace.
Quick quiz