Chapter 4 · concept 2 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Structure aware chunking and tables
Splitting documents along their own headings and keeping tables whole, and why structure alone did not win on our table questions.
A real question
I split my documents by headings and every table stayed whole. Why is a table answer still missed?
Keeping a table whole stops it being cut, but a chunk that is only numbers shares few words with the question, so it can rank low.
The problem
Why this matters
Split by headings, keep tables whole, and table questions are solved.
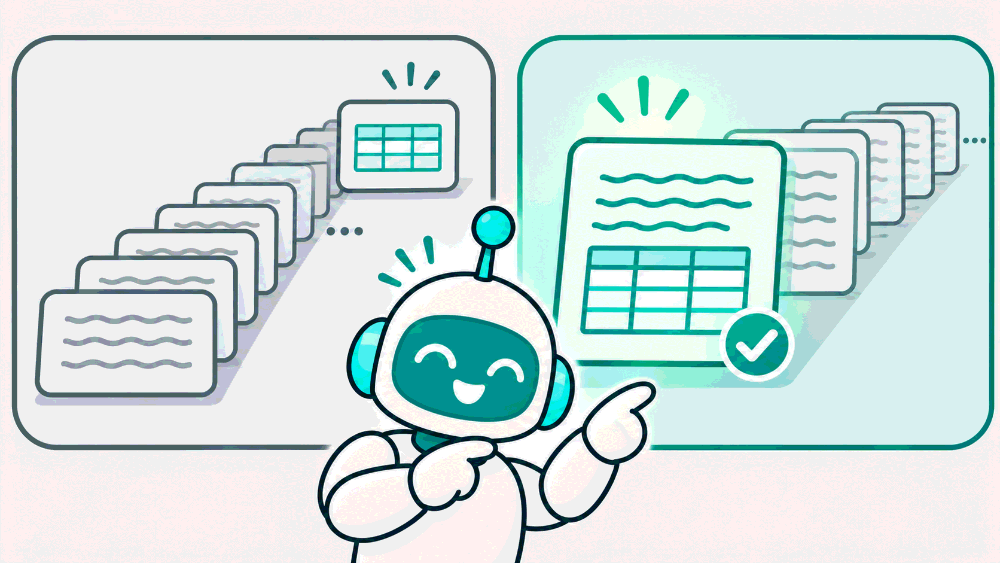
It solved cutting, not finding. On our bank report, the whole “Key figures” table ranked 14th for “net profit in 2025”. With the surrounding text in the same chunk, it ranked 1st.
Why not the simpler way
The simple way treats a document as a flat string. That is fine for prose. Manuals, annual reports and policies are not flat: they have sections, numbered clauses and tables. A fixed window cuts a table row from its header, or a clause from the heading that says which product it is about, and the answer arrives without the context that makes it true.
The idea
The idea in plain words
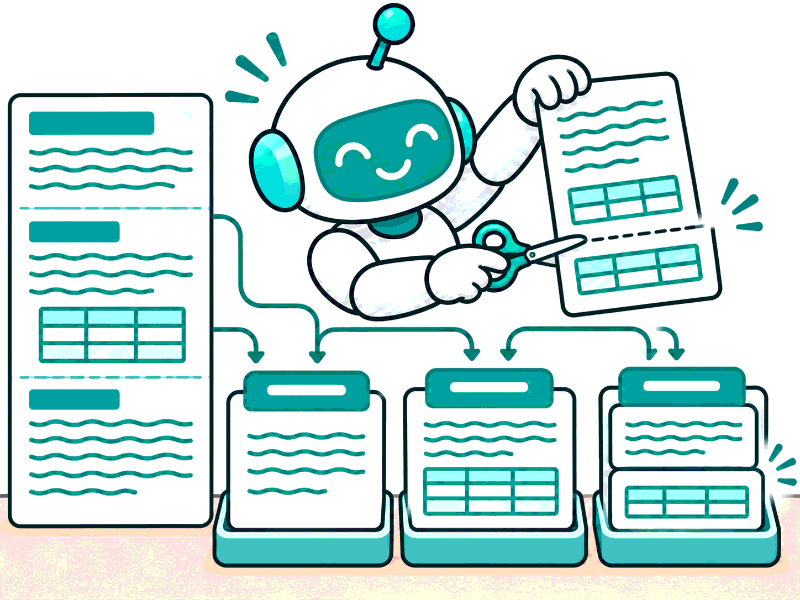
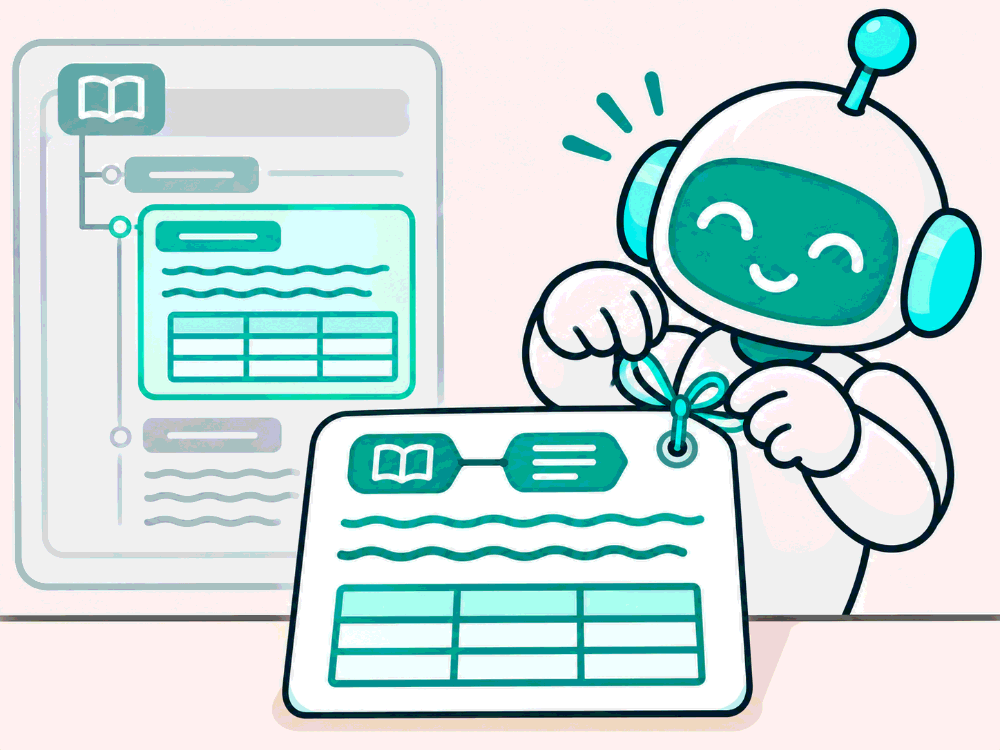
Structure aware chunking uses the document's own shape. Each section, under its heading, becomes a chunk. A table stays in one chunk, or is split by rows with the header repeated. Each chunk also carries its heading path, such as "FiberBox manual > 3. Error codes", so you know where it came from.
Think of a newspaper. You clip whole articles, not every tenth line, and you write the section name on each clipping.
How it works
Step by step
 1
Read the document's blocks
Headings, paragraphs, lists and tables, each recognised from the markup.
 2
Group under the nearest heading
A section that fits becomes one chunk. Long sections are split, tables only between rows.
 3
Keep the heading path
Store “Bank report > 2. Key figures” with the chunk, for citations and for context.
In detail
Parse the document into blocks: headings, paragraphs, lists, tables, code. Group blocks under their nearest heading. If a section fits the size limit, it is one chunk. If not, split it recursively, and split tables only between rows, copying the header row into each part.
Structure is not the whole story. A short section makes a short chunk, and many short chunks compete for the same top 3. On our corpus the heading-based setting produced 91 chunks against 33 for recursive 512, and on table questions it ranked two answer chunks below the top 3.
The code
Try it in Python
def split_table(lines: list[str], max_rows: int) -> list[str]:
    """Split a markdown table between rows, repeating the header in each part."""
    header, sep, rows = lines[0], lines[1], lines[2:]
    return ["\n".join([header, sep, *rows[i:i + max_rows]]) for i in range(0, len(rows), max_rows)]

table = ["| Code | Meaning |", "| --- | --- |", "| E1001 | Power unstable |", "| E4012 | Mesh pairing failed |"]
for part in split_table(table, max_rows=1):
    print(part, "\n")
See it
What we measured
Measured · table questions with the answer passage in the top 3
The 8 golden questions whose answer sits in a table (FiberBox manual and Polder Bank annual report), vector search with bge-small-en-v1.5.
Measured 2026-11-03 on the precomputed vectors. Only fixed 128 split a table. By headings kept every table whole but ranked two of them below the top 3, so structure fixed splitting and did not fix ranking.
Try it on a real example
A real question: “What was Polder Bank's net profit in 2025?”
Chunk “2. Key figures” · 264 tokens · rank 14
The table is whole, but it is mostly numbers. Thirteen chunks with more matching words ranked above it.
Choosing
Use it when, avoid it when
- Manuals, policies and reports with reliable headings
- Any table: keep it whole or split by rows with the header repeated
- Trusting structure from a PDF parser without checking a sample
- Very short sections as their own chunks: merge them upward
What it costs · Structure aware chunking needs a parser per format and more chunks to store. Here 91 chunks against 33 for recursive 512.
In production
Use structure where it exists and is reliable: markdown, HTML, well tagged documents. For PDFs, structure comes from the parser and can be wrong, so check a sample (see RAG-08). Merge very short sections with their neighbour or parent heading, and always keep the heading path as metadata. Test table questions separately: they fail in their own ways.
Watch out
Common mistakes
- Structure aware chunking always wins. It stopped splits; it did not stop ranking misses.
- Tables are just text. Without the header row, the numbers in a row have no meaning.
- Headings are only for display. They are the best context a chunk can carry.
Check yourself
Remember this
Remember these
- Structure-aware chunking follows headings and keeps tables whole.
- Split large tables between rows and repeat the header.
- On 8 table questions: by headings found 6, recursive 512 found 8.
- Very short sections make weak chunks: merge them with their neighbours.
Say it in an interview
- 01Structure aware chunking splits along headings and keeps tables whole.
- 02When a table must be split, I split between rows and repeat the header.
- 03On my 8 table questions, fixed 128 found 5 and cut 2 tables; recursive 512 found 8.
- 04By headings kept every table whole but found only 6: short sections hurt ranking.
- 05I keep the heading path on every chunk and test table questions on their own.
Quick quiz