Chapter 5 · concept 3 of 4 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Choosing an embedding model: size, cost, language
Four open models scored on our own 47 questions and 8 Dutch translations. The largest came last, the multilingual one came first, and the leaderboard would not have told us.
A real question
There are hundreds of embedding models. Is the biggest one the safest choice?
Not on our corpus. We scored four open models on the same 47 questions. The largest English model found the fewest answers; a small multilingual model found them all.
The problem
Why this matters
A bigger model with more dimensions always retrieves better.
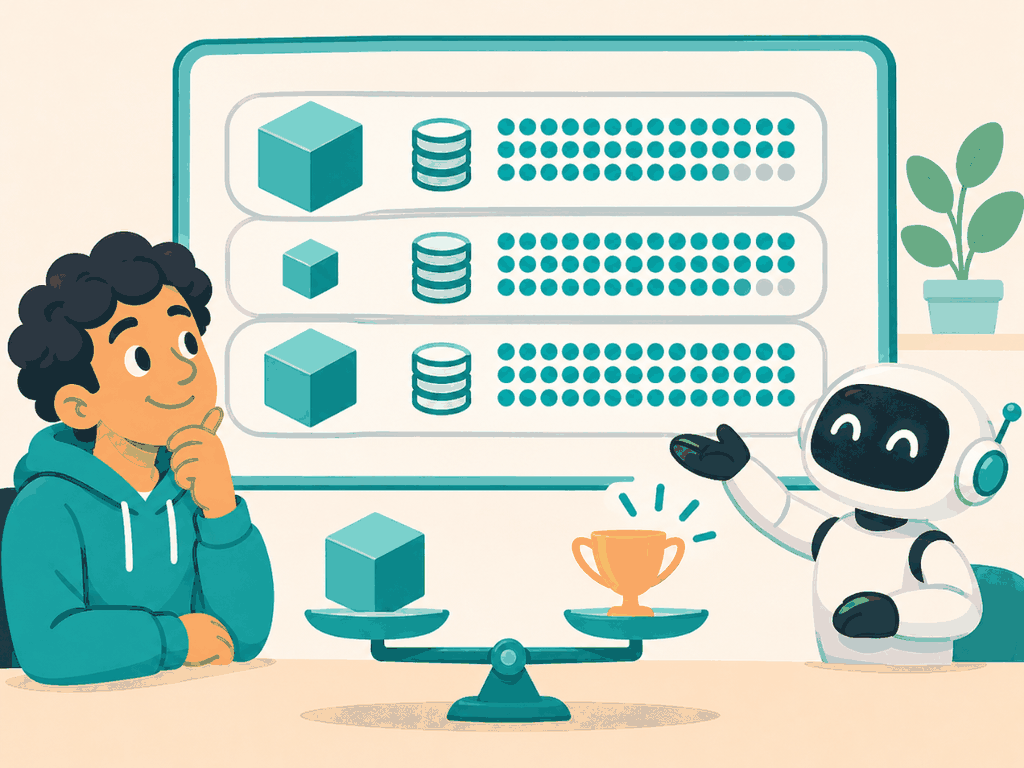
bge-base (110 MB, 768 dims) found 44 of 47, behind all-MiniLM (23 MB) with 45. multilingual-e5-small (118 MB, 384 dims) found 47 of 47. The size of the model did not predict the result.
Why not the simpler way
Choosing an embedding model is often a guess: the top of a public leaderboard, or whatever a tutorial used. The choice is expensive to undo, because changing the model means re-embedding everything (RAG-25). It deserves a measurement, and the measurement is cheap.
The idea
The idea in plain words
Treat model choice like hiring: a shortlist from public information, then the same test for every candidate, on your real work. The test is your golden set (RAG-40): questions with a known answer passage. The score is how often that passage lands in the top 3.
A car review tells you which cars are good in general. A test drive on your own commute tells you which car is good for you.
How it works
Step by step
 1
Use your own data
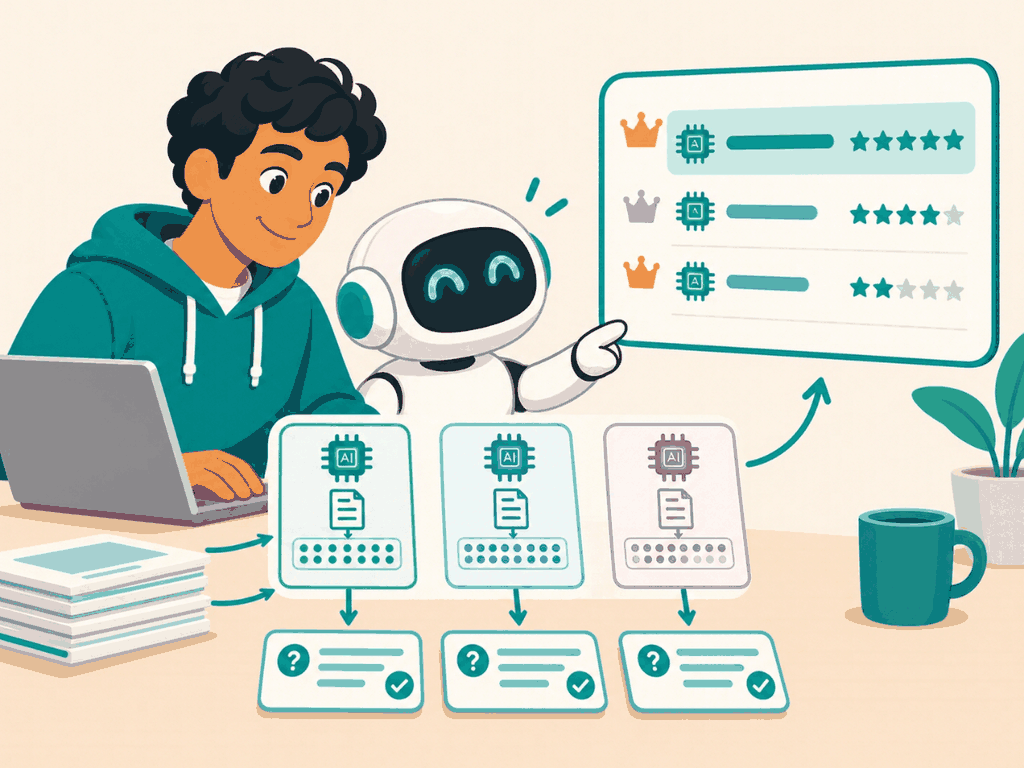
Embed your chunks with each candidate, and ask your golden questions. A leaderboard is only a shortlist.
 2
Score everything the same way
Same chunks, same metric (evidence in the top 3), plus size, speed, languages, licence and maximum input length.
 3
Pick the smallest that passes
Set the bar first. The cheapest model that clears it is the right one; you can switch later with a planned migration.
In detail
What to compare. Quality on your questions; model size (download and memory); dimensions (storage per vector and search cost); maximum input tokens (512 for the bge and e5 models; all-MiniLM-L6-v2 cuts input at 256 by default, per its model card); languages; licence; and whether it runs where you need it, on a server, in the browser or through an API.
Prefixes and pooling. Each model has its own recipe. bge wants a query instruction and CLS pooling; e5 wants "query: " and "passage: " and mean pooling; MiniLM wants neither. A wrong recipe makes a good model look bad.
Public benchmarks. MTEB ranks models across many retrieval tasks. Use it to pick candidates, then measure. Its average hides your domain, your language and your question style.
The code
Try it in Python
CANDIDATES = {
    "BAAI/bge-small-en-v1.5": ("Represent this sentence for searching relevant passages: ", ""),
    "sentence-transformers/all-MiniLM-L6-v2": ("", ""),
    "intfloat/multilingual-e5-small": ("query: ", "passage: "),
}

def recall_at_3(name, q_prefix, p_prefix, chunks, golden):
    m = SentenceTransformer(name)
    docs = m.encode([p_prefix + c for c in chunks], normalize_embeddings=True)
    hits = 0
    for g in golden:
        q = m.encode(q_prefix + g["question"], normalize_embeddings=True)
        top = np.argsort(-(docs @ q))[:3]
        hits += any(g["evidence"] in chunks[i] for i in top)
    return hits / len(golden)

for name, (qp, pp) in CANDIDATES.items():
    print(name, recall_at_3(name, qp, pp, chunks, golden))
See it
What we measured
Measured · evidence recall@3, recursive 512 token chunks
Polder corpus, 34 chunks, 47 golden questions; 8 of them translated into Dutch by us. All models q8 ONNX via transformers.js, each with its own prefix and pooling. Sizes are the downloaded quantized weights.
Measured 2026-11-04 with corpus/scripts/measure-parts-4-7.mts. bge-small scores 44 of 47 with the vectors stored for the labs and 43 when re-embedded in this run; q8 rounding moves one close call. 47 questions is a small set, so treat 1 or 2 questions as noise.
Try it on a real example
Four models, the same 34 chunks and 47 questions
The order by size and the order by results do not match.
Choosing
Use it when, avoid it when
- Your golden set as the deciding test
- A multilingual model when users or documents mix languages
- Choosing by leaderboard rank or size alone
- Comparing models with the wrong prefix or pooling
What it costs · An afternoon: embed the corpus once per candidate. Changing later costs a full re-embed and a migration (RAG-25).
In production
Hosted embedding APIs remove the hardware question but add a per-token price, a network call per query and a dependency on the vendor keeping the model available. Local models cost compute you run yourself. Whichever you choose, record the model name, version, prefix and pooling next to each vector, so a later migration knows what it is replacing. Re-run the comparison when your corpus changes language or domain.
Watch out
Common mistakes
- More dimensions, better search. The 768-dimension model came last here.
- English models handle a bit of Dutch. They found 3 or 4 of 8 Dutch questions; the multilingual model found 7.
- One run settles it. With 47 questions, a gap of one question can come from rounding alone.
Check yourself
Remember this
Remember these
- Shortlist from a leaderboard, decide on your own golden questions.
- Compare size, dimensions, languages, maximum tokens and licence, not just quality.
- If users ask in another language, test that language on purpose.
- Differences of one or two questions out of 47 are noise; look for clear gaps.
Say it in an interview
- 01I shortlist from MTEB, then decide on my own golden set.
- 02On my corpus the 110 MB bge-base found 44 of 47, the 23 MB MiniLM 45; the multilingual e5-small found 47 of 47.
- 03I also test the languages users actually ask in: Dutch questions split the models clearly.
- 04Each model has its own prefix and pooling; getting those wrong makes a good model look bad.
- 05I store the model name and recipe with the vectors so a migration is planned, not guessed.
Quick quiz