Chapter 7 · concept 2 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Dense retrieval and keyword search with BM25
How BM25 scores shared rare words, how dense retrieval scores meaning, and a head to head on our 47 questions where the 30 year old method won, with the reason why.
A real question
Vector search understands meaning. Is keyword search still worth having?
Yes. On our corpus BM25, a keyword method from the 1990s, found all 47 answers in the top 3 and vector search found 44. Each catches questions the other misses.
The problem
Why this matters
Vector search replaced keyword search.
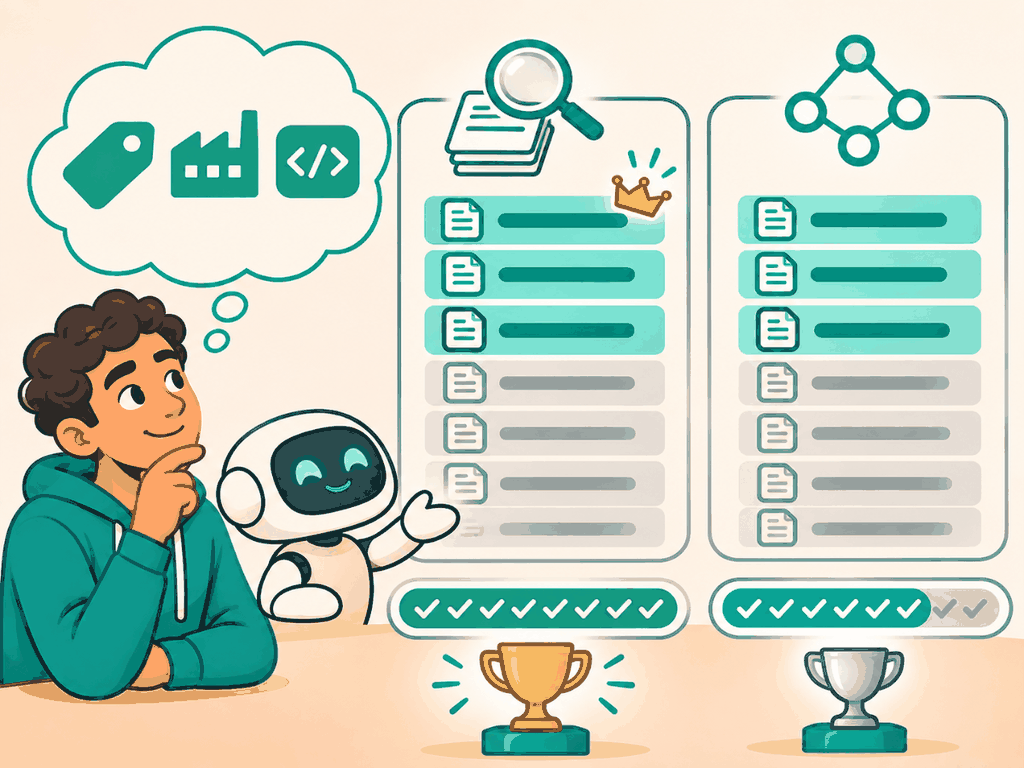
BM25 put the answer in the top 3 for 47 of 47 questions and first for 35. Vector search: 44 and 30. Rare exact words like “excess”, “RTO” or “E4012” are BM25's strength.
Why not the simpler way
After learning embeddings it is tempting to drop keyword search. Then questions about a product code, a regulation number or an unusual term start failing, because the vector smooths them into a topic. Understanding both methods tells you what each one is for.
The idea
The idea in plain words
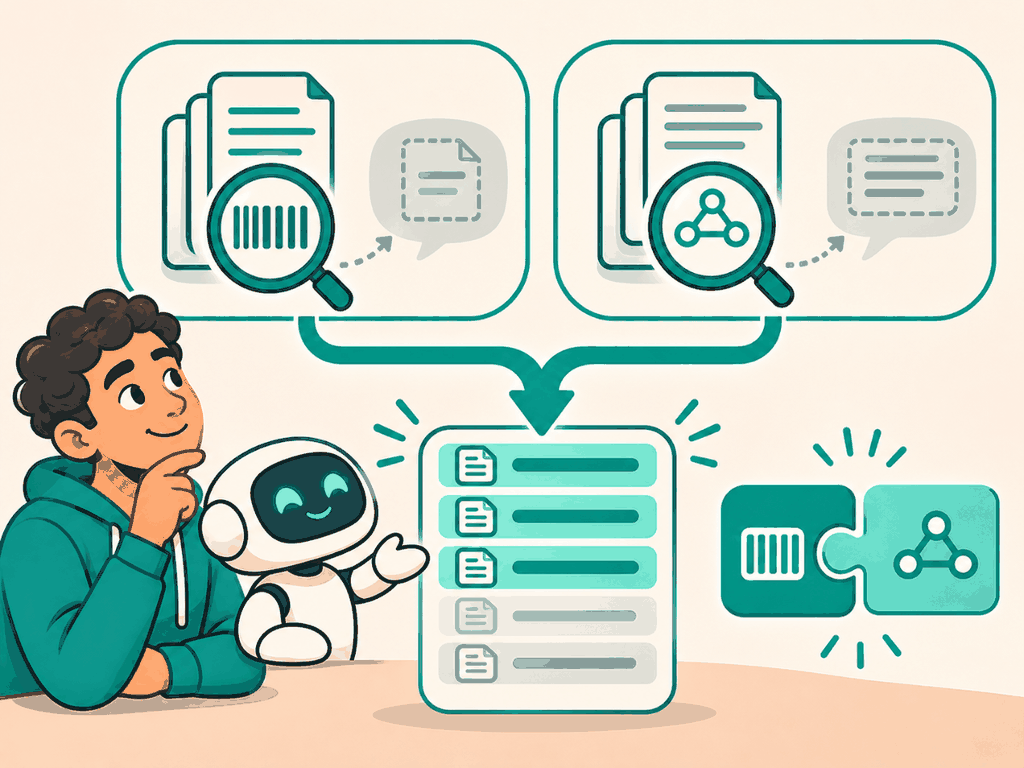
BM25 is a keyword ranking function. For every word in the question it asks: does this chunk contain it, how often, how rare is the word across all chunks, and how long is the chunk? It adds that up. Dense retrieval embeds question and chunks and ranks by cosine (RAG-19).
BM25 is a search for an exact name in a phone book. Dense retrieval is asking a friend "who was that plumber who fixed the leak?".
How it works
Step by step
 1
BM25 counts rare shared words
Each word the question and chunk share adds to the score, more if the word is rare in the corpus, less if the chunk is long.
 2
Vectors match meaning
Dense retrieval compares embeddings, so “restart modem” finds “reboot the router” with no shared words.
 3
Each covers the other's gap
BM25 misses paraphrases; vectors blur codes and rare terms. That is why most systems run both (RAG-28).
In detail
The BM25 formula, in words. For each query word: IDF (rarer words count more) times a saturating term frequency (the 5th mention adds less than the 1st), divided by a length factor (long chunks are penalized). Two settings: k1 (how fast frequency saturates, we use 1.2) and b (how strongly length matters, we use 0.75).
Tokenization matters. BM25 sees words as your tokenizer splits them. Our tokenizer splits on hyphens, so "PT-MOB-25GB" becomes three tokens; that still matched here, but a tokenizer that drops digits or short tokens would lose codes like "E4012" or "1012". Stemming and stop words change results; test them.
Dense retrieval needs an embedding model and an index (RAG-22); BM25 needs an inverted index, which every search engine has.
The code
Try it in Python
import math, re
from collections import Counter

def tokens(text: str) -> list[str]:
    return re.findall(r"[a-z0-9][a-z0-9-]*", text.lower())   # keeps E4012 and PT-MOB-25GB whole

def bm25_index(chunks, k1=1.2, b=0.75):
    docs = [Counter(tokens(c)) for c in chunks]
    avg = sum(sum(d.values()) for d in docs) / len(docs)
    df = Counter(t for d in docs for t in d)
    idf = {t: math.log(1 + (len(docs) - n + 0.5) / (n + 0.5)) for t, n in df.items()}
    def score(query: str):
        q = tokens(query)
        out = []
        for d in docs:
            L = sum(d.values())
            out.append(sum(idf.get(t, 0) * d[t] * (k1 + 1) / (d[t] + k1 * (1 - b + b * L / avg)) for t in q))
        return out
    return score
See it
What we measured
Measured · retrieval on 47 golden questions
Polder corpus, 34 recursive 512 token chunks. BM25: k1 1.2, b 0.75, lowercase, split on anything that is not a letter or digit (so PT-MOB-25GB becomes pt, mob, 25gb). Vector: bge-small. A hit is a chunk holding the evidence quote.
Measured 2026-11-04 with corpus/scripts/measure-parts-4-7.mts. The golden questions were written while reading the documents, which favours keyword overlap.
Try it on a real example
“Is there an excess for storm damage?”
Vector search finds the insurance documents, but the one sentence with the answer is sixth.
Choosing
Use it when, avoid it when
- BM25 for codes, IDs, names and rare terms
- Dense retrieval for paraphrases, synonyms and other languages
- Both, fused, as the default (RAG-28)
- Dropping BM25 because vectors feel modern
- Judging either on questions written from the documents only
What it costs · BM25: an inverted index, no model. Dense: an embedding model and a vector index.
In production
BM25 is cheap, explainable (you can show which words matched) and needs no model. It fails on synonyms, other languages and vague questions. Dense retrieval fails on exact identifiers and rare terms. In production, measure both on your golden set, split by slice: codes, paraphrases, languages. Add paraphrased questions to the golden set on purpose, because questions written from the documents flatter BM25.
Watch out
Common mistakes
- BM25 is obsolete. It beat vectors on our corpus.
- Vector search finds everything BM25 finds. It ranked the storm excess sentence sixth.
- BM25 won, so drop vectors. Vectors ranked the answer higher on 5 questions, and real users paraphrase more than our golden set.
Check yourself
Remember this
Remember these
- BM25 scores shared words, weighted by rarity and chunk length.
- Dense retrieval scores meaning and handles paraphrases.
- On our 47 questions: BM25 47 in the top 3, vectors 44.
- Our questions share words with the documents; real users paraphrase more.
Say it in an interview
- 01BM25 scores shared words by rarity, frequency and chunk length; vectors score meaning.
- 02On my corpus BM25 put 47 of 47 answers in the top 3 and vectors 44.
- 03BM25 wins on rare exact terms like excess, RTO or product codes.
- 04My golden questions share words with the documents, so I add paraphrases to be fair.
- 05I run both and fuse them, because they fail on different questions.
Quick quiz