Chapter 10 · concept 4 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Faithfulness and answer correctness
Two different questions about an answer: is it true (correctness), and does it come from the sources (faithfulness)? How to measure each, from cheap string checks to claim-by-claim judging.
A real question
The answer is right. Is that enough?
Not for RAG. Ask two things: is it correct, compared with the golden answer, and is it faithful, meaning every claim is backed by the retrieved sources? An answer can pass one and fail the other.
The problem
Why this matters
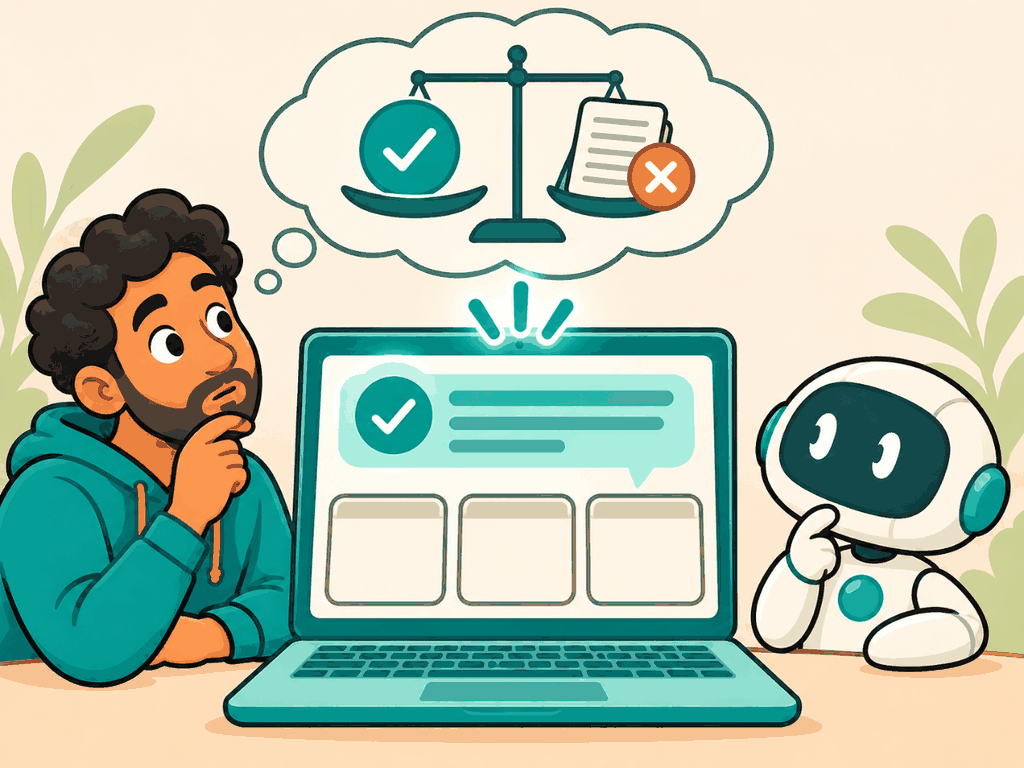
A correct answer is automatically a faithful one.
A model can answer correctly from memory with sources that say nothing, or answer faithfully from the wrong version. The first passes correctness and fails faithfulness; the second passes faithfulness and fails correctness.
Why not the simpler way
Retrieval metrics (RAG-41) say whether the right chunk reached the model. They do not say what the model did with it. Answer-level metrics close that gap, and they are harder, because answers are free text.
The idea
The idea in plain words
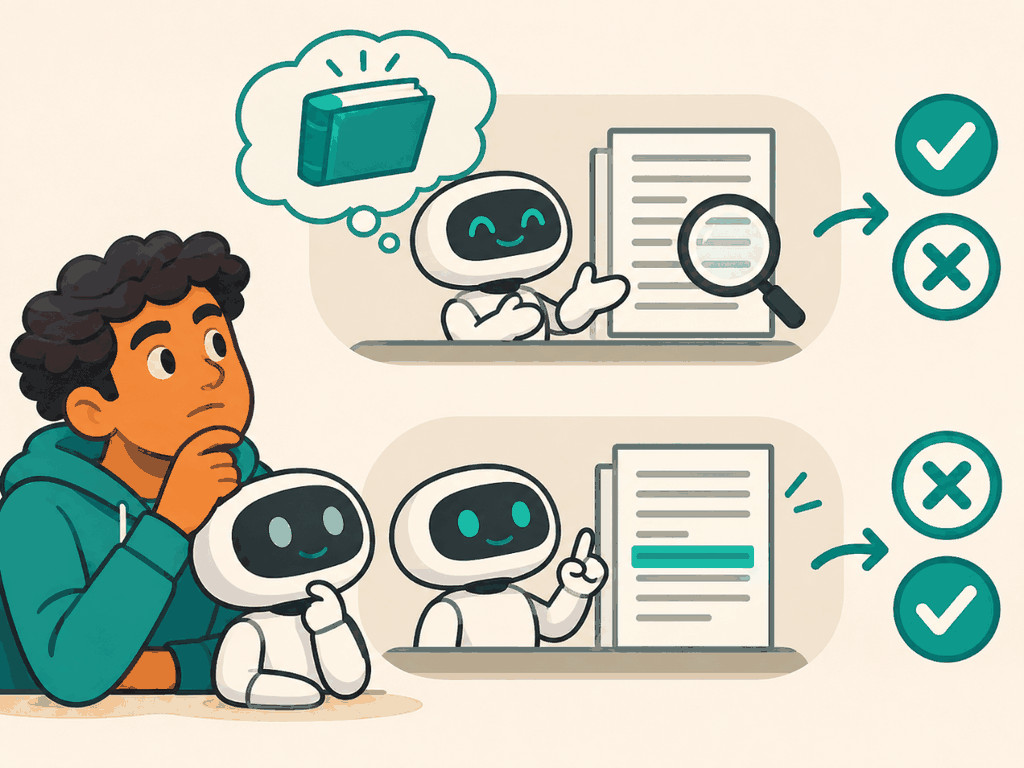
Answer correctness: does the answer agree with the expected answer? Faithfulness (also called groundedness): is every claim supported by the context the model was given? Answer relevance: does it answer the question asked? Frameworks such as RAGAS (Es et al., arXiv 2309.15217) define these with a model as the judge.
A student's essay can be accurate but copied from memory instead of the assigned reading, or faithful to the reading and still miss the question.
How it works
Step by step
 1
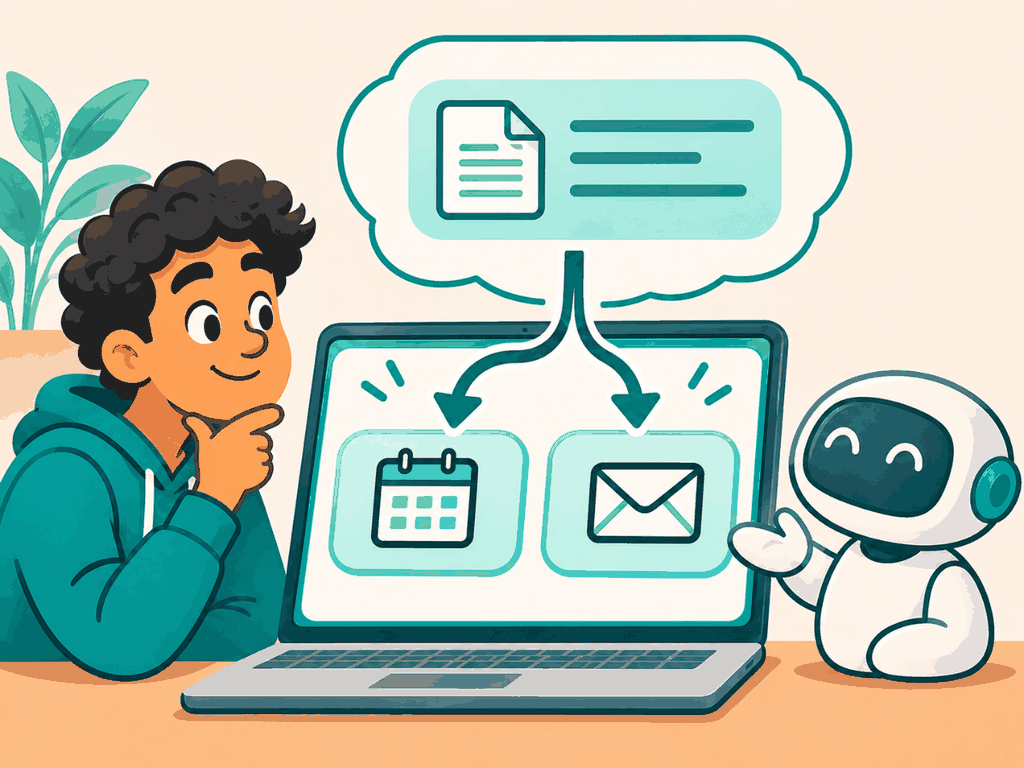
Split into claims
Break the answer into short factual statements: “notice is 30 days”, “notice is sent by e-mail”.
 2
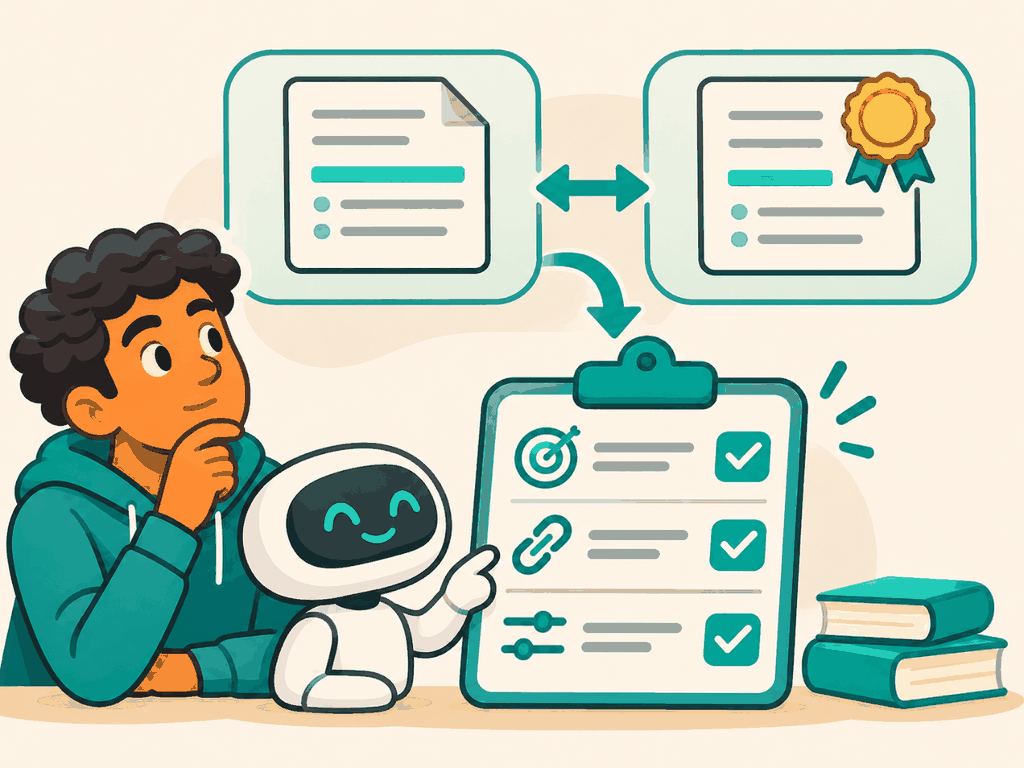
Check each against the context
Faithfulness: the share of claims supported by the retrieved sources. Values by string match; the rest by a judge (RAG-43).
 3
Compare with the golden answer
Correctness: do the answer's key facts match the expected answer? Exact values first, then meaning.
In detail
Exact checks first. For golden answers with values, check the model's answer contains them; and that each value is in the cited source (RAG-37). On our expected answers, the value check passed 38 of 39.
Claim-level faithfulness. A model splits the answer into claims, then judges each claim as supported or not by the context. Score = supported / total.
Semantic correctness. A model compares answer and golden answer for meaning. Use a narrow rubric and check the judge (RAG-43).
Abstention. For unanswerable golden items, the correct answer is the abstain phrase (RAG-34).
The code
Try it in Python
import re

def key_values(text: str) -> set[str]:
    text = re.sub(r"(\d)[, ](?=\d{3}\b)", r"\1", text)
    return set(re.findall(r"[A-Z]{1,4}-?\d[\w.-]*|\d+(?:\.\d+)?", text))

def value_correct(answer: str, golden_answer: str) -> bool:
    return key_values(golden_answer) <= key_values(answer)

JUDGE = """Claims: {claims}
Context: {context}
For each claim answer SUPPORTED or NOT_SUPPORTED, using only the context."""
# faithfulness = supported claims / all claims, judged by a model you have checked (RAG-43)
See it
What we measured
Measured · value checks on the golden set's expected answers
47 answerable golden questions; hybrid top-3 context; numbers normalized for thousands separators.
Measured 2026-11-04 with corpus/scripts/measure-parts-6-7.mts. Model answers need model calls: not measured yet, needs an API key, using the Mini RAG Lab prompt.
Try it on a real example
Three answers we wrote to show each case. Golden for the first two: 30 days, by e-mail.
Context: tariff sheet 2026.1
Both claims are in source [1] and match the golden answer.
Choosing
Use it when, avoid it when
- Exact value checks for correctness and faithfulness
- Claim-level judging for text answers, on a schedule
- Only measuring correctness
- Trusting a judge you have not compared with human labels
What it costs · Value checks are free. Claim judging costs one or two model calls per answer.
In production
Run exact checks on every answer in CI and on sampled traffic. Run model-judged faithfulness on the golden set before releases and on a daily sample, since each judgement is a model call. Track faithfulness per model and prompt version; a new model that is "smarter" may lean on memory more.
Watch out
Common mistakes
- Correct means faithful. Memory answers can be correct and unchecked.
- Faithful means correct. Faithful to an outdated source is still wrong.
- Answer metrics replace retrieval metrics. They answer a different question; keep both.
Check yourself
Remember this
Remember these
- Correctness compares the answer with the golden answer.
- Faithfulness checks every claim against the retrieved context.
- Start with exact value checks; add claim judging where values are not enough.
- Report both, plus abstention on unanswerable questions.
Say it in an interview
- 01I measure correctness against the golden answer and faithfulness against the retrieved context.
- 02Exact value checks come first: cheap, deterministic, run on every answer.
- 03Claim-level faithfulness uses a model judge that I validate against human labels.
- 04A correct answer from memory is still a failure in RAG, because no source backs it.
- 05Unanswerable golden items test that the model abstains.
Quick quiz