Chapter 11 · concept 5 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Latency, cost, caching and model routing
Measure where time and money go before tuning. In our pipeline the reranker took 1.4 s and search under a millisecond; on input cost, RAG cut a question from $0.031 to $0.0043, and a smaller model would cut it about 40 times more.
A real question
Answers take too long and cost too much. Where do you start?
With a measurement. Time every stage and count tokens per request. Then cut the biggest cost first, often the reranker or the model call, not the search people suspect.
The problem
Why this matters
Search is the slow part of RAG.
On our pipeline, embedding the question took 3.4 ms and both searches under 0.1 ms. Reranking 10 candidates took 1,406 ms. The model call, not measured here, is usually the other big one.
Why not the simpler way
Cost and latency decide whether a RAG system can launch at all. A slow answer is abandoned; an expensive one cannot scale. Both are easy to guess wrong, because the slow part is not always where intuition points.
The idea
The idea in plain words
Latency budget: the total time a user will wait, split across stages. Cost per request: tokens times price, plus reranking and embedding. Caching: reuse what does not change, from the prompt prefix to whole answers (RAG-30). Model routing: pick a model per request based on how hard it is.
A restaurant times each station in the kitchen before hiring more cooks. The slow station is not always the stove.
How it works
Step by step
 1
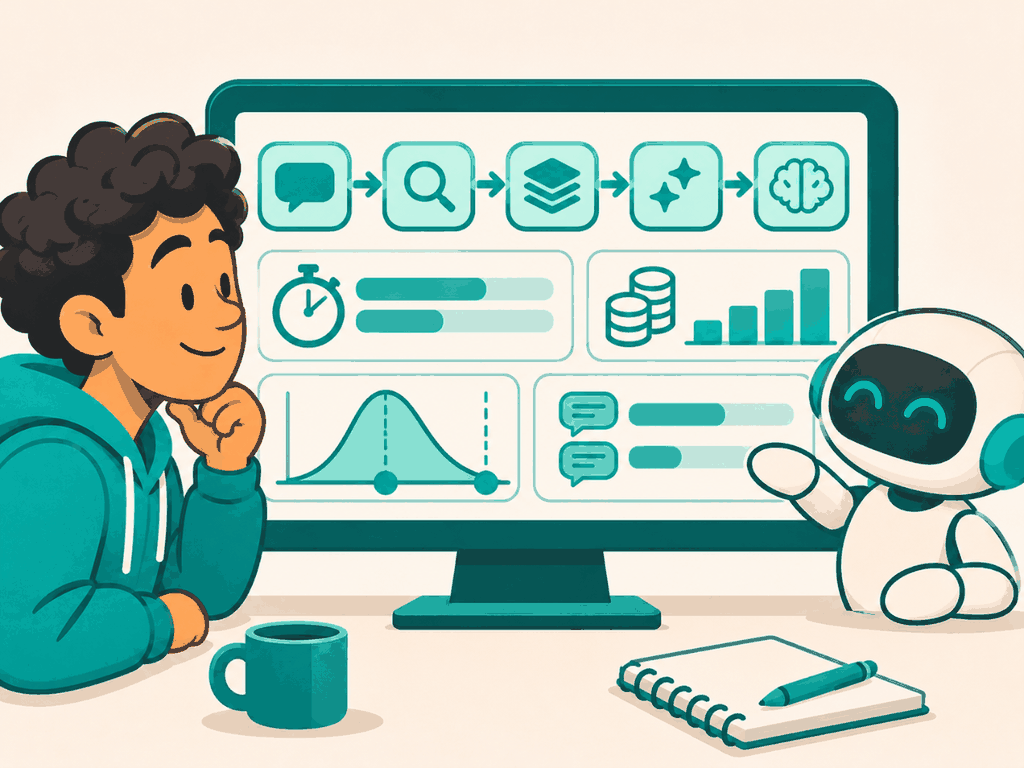
Measure first
p50 and p95 latency per stage (RAG-48), input and output tokens per request, cost per request by model.
 2
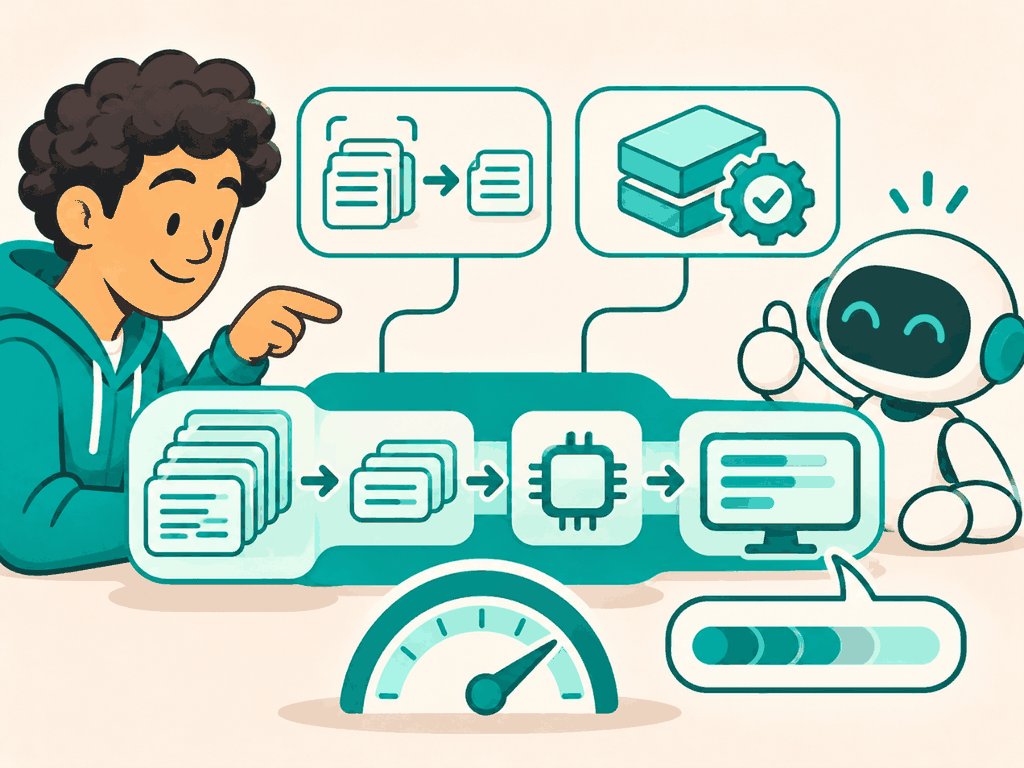
Cut the biggest cost
Fewer rerank candidates or faster hardware; small k and short contexts; prompt caching for the fixed parts; streaming so users see text sooner.
 3
Route by difficulty
Send simple, well-grounded questions to a small model and hard ones to a large one. Measure quality per route on the golden set.
In detail
Rerank cost. Linear in candidates: rerank 10, not 50, unless measurement shows a gain; run on a GPU or use a hosted reranker.
Tokens. Context is usually the largest input. k from a recall curve (RAG-29), dedup, short chunk headers. Output tokens cost more per token than input; ask for short answers.
Prompt caching. Put stable content (system rules, tool definitions) first so it can be cached; the vendor charges cache reads at a fraction of input price ($0.20 against $4 per million for Opus 5.5, checked 2026-11-03).
Routing. Rules (question length, presence of codes, retrieval confidence) or a small classifier. Fall back to the larger model on low verification scores (RAG-37).
Streaming. Does not lower total time, but users see the first words sooner.
The code
Try it in Python
PRICES = {"claude-opus-5-5": (4.00, 20.00), "claude-haiku-5-5": (0.10, 0.50)}   # $ per M tokens, in/out

def cost(model: str, tokens_in: int, tokens_out: int) -> float:
    pin, pout = PRICES[model]
    return (tokens_in * pin + tokens_out * pout) / 1_000_000

def route(question: str, top_score: float, has_code: bool) -> str:
    if has_code or top_score >= 0.75:      # well grounded, look-up style
        return "claude-haiku-5-5"
    return "claude-opus-5-5"               # vague or multi-part: the larger model

print(round(cost("claude-opus-5-5", 1078, 0), 4), round(cost("claude-haiku-5-5", 1078, 0), 6))
See it
What we measured
Measured · latency per stage and input cost per question
Latency: median over 47 golden questions, laptop CPU. Cost: list prices checked 2026-11-03, input tokens only, measured token counts from RAG-04.
Latency measured 2026-11-04 with corpus/scripts/measure-part-8.mts; costs calculated from measured tokens. Model latency and output cost need model calls: not measured yet. Answer quality on Haiku was not measured.
Try it on a real example
Input cost of one question, list prices, from measured token counts
Opus 5.5, about 7,650 input tokens
$0.031 per question (RAG-04). With caching while warm: $0.0017.
Choosing
Use it when, avoid it when
- Per-stage timing and per-request cost before any tuning
- Small k, prompt caching and routing where the golden set agrees
- Optimising search when the reranker or model dominates
- Routing to a small model without measuring quality
What it costs · Measuring is cheap. Routing adds a decision step and a second model to test.
In production
Set budgets: for example p95 under a few seconds and a cost ceiling per 1,000 questions, and alert when a release breaks them. Watch the long tail: a few questions with huge contexts or many agent steps can dominate cost. Re-check routing quality whenever models or prices change.
Watch out
Common mistakes
- A faster vector database fixes latency. Our search was under 0.1 ms.
- The cheapest model is false economy. It may be right for simple questions; measure.
- Streaming makes it faster. It makes it feel faster.
Check yourself
Remember this
Remember these
- Time every stage and count tokens before tuning.
- Our reranker was 1.4 s; search was under a millisecond.
- Smaller contexts and smaller models cut cost the most.
- Route by difficulty, and check quality per route on the golden set.
Say it in an interview
- 01I measure per-stage latency and per-request tokens before tuning anything.
- 02In my pipeline reranking 10 candidates took 1.4 s; search took under a millisecond.
- 03RAG cut input cost per question from $0.031 to $0.0043 on Opus; Haiku would be about $0.0001.
- 04I cache stable prompt prefixes and keep k small.
- 05Routing to a smaller model is an experiment, kept only if the golden set holds.
Quick quiz