Chapter 9 · concept 3 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Lost in the middle and context management
Models use the start and end of a long context better than the middle. Where our answers land in the context, and how ordering, short contexts and trimmed history keep the answer where the model looks.
A real question
The right chunk is in the prompt. Can the model still miss it?
Yes. Studies show models use information at the start and end of a long context better than in the middle. Keep contexts short, put the best chunk first, and trim what does not help.
The problem
Why this matters
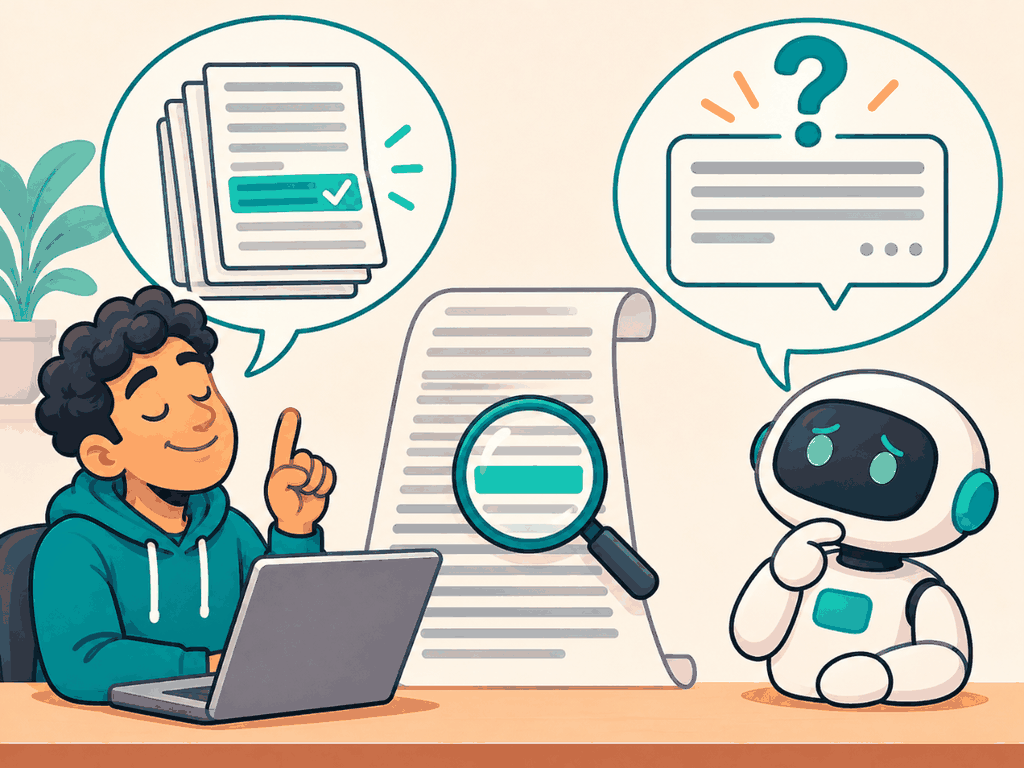
If the answer is anywhere in the context, the model will use it.
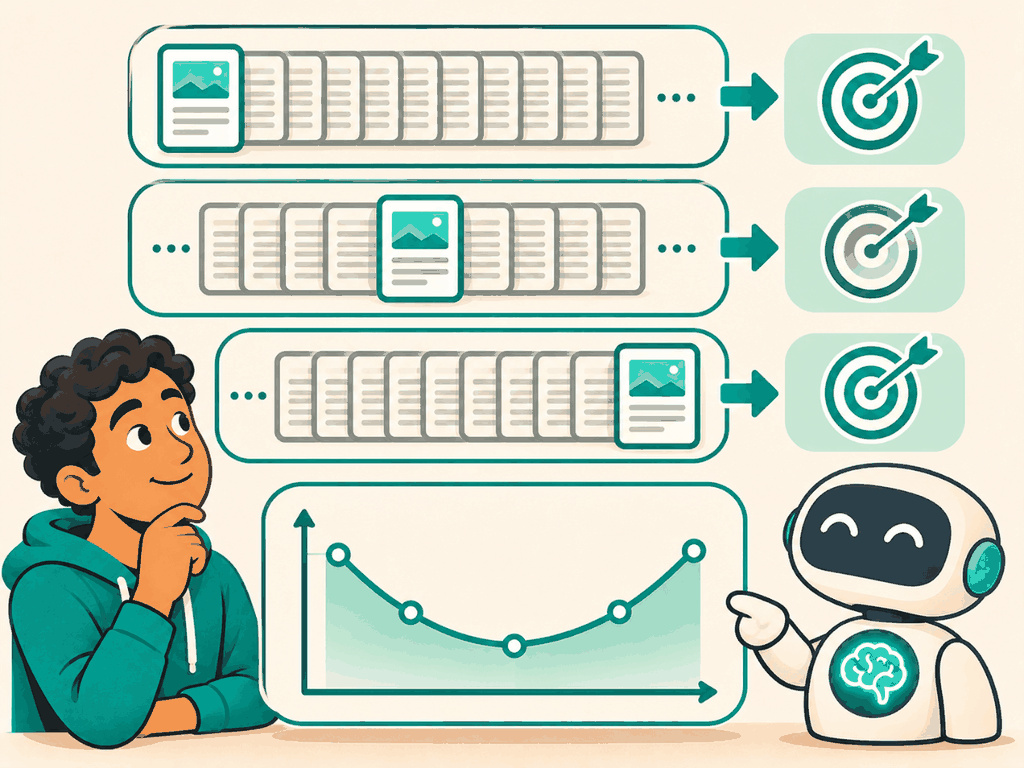
In the “Lost in the Middle” experiments, accuracy dropped when the answer document sat in the middle of 20 documents, compared with the start or end. Position matters, more so as the context grows.
Why not the simpler way
Long context windows invite a simple strategy: retrieve a lot, paste it all, let the model find the answer. It costs more per question, and it gives the model a harder reading task. Evidence from several studies says models do not read long contexts evenly.
The idea
The idea in plain words
Lost in the middle (Liu et al., "Lost in the Middle: How Language Models Use Long Contexts", arXiv 2307.03172, 2023) put the answer document at different positions among 10 to 30 documents. Accuracy formed a U: best at the start, good at the end, worst in the middle. Newer models handle long contexts better, but position effects remain worth testing on your own model.
Context management keeps the prompt focused: what to keep, in what order, and what to summarize or drop.
When you skim a long email, you read the opening and the sign-off carefully and skim the middle.
How it works
Step by step
 1
Know where answers land
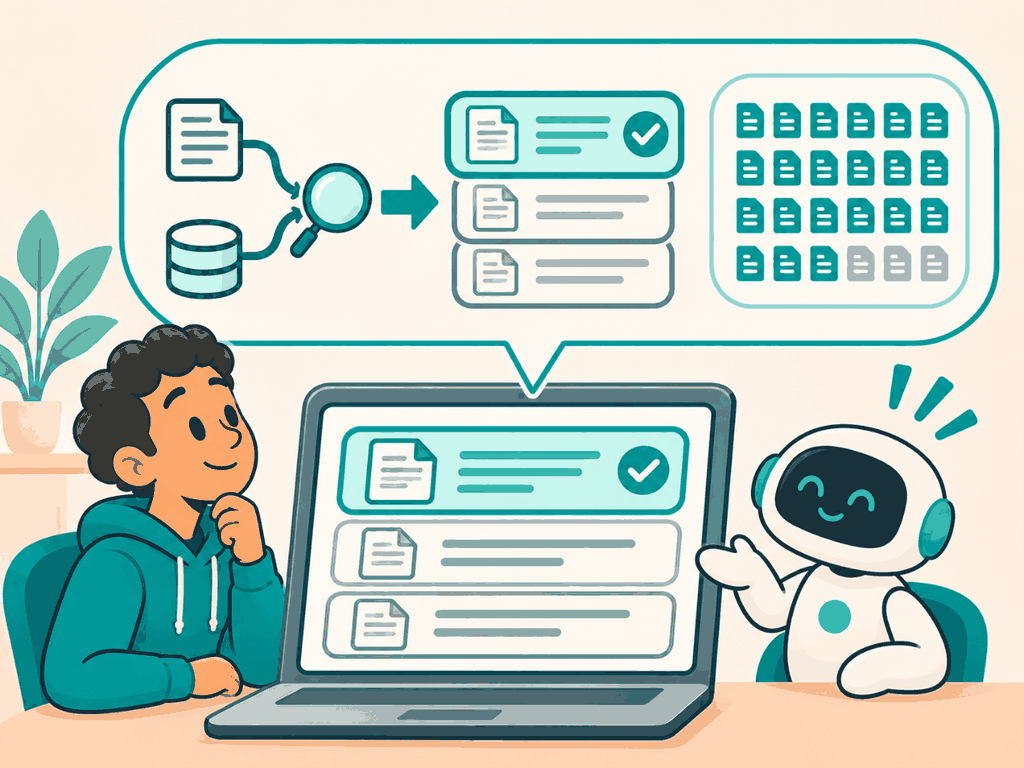
With hybrid search, our answer chunk was first in the context for 33 of 47 questions and never below third.
 2
Best first, few chunks
Order by reranker score, keep k small. A short context has no middle to get lost in.
 3
Manage the rest
In chat, summarize old turns instead of keeping them all. Drop chunks the answer does not need.
In detail
Ordering. Best first. Some systems put the second best last, so both ends hold strong chunks.
Size. Retrieve wide, rerank, pass few (RAG-29, RAG-31).
Conversation history. Keep the last few turns verbatim, summarize older ones, and drop old retrieved chunks unless the follow-up needs them. Rewrite follow-ups into stand-alone questions before search (RAG-38).
Compression. Extract only the relevant sentences from each chunk before packing. It saves tokens and can lose context; measure it.
The code
Try it in Python
def order_for_model(chunks_best_first: list[str]) -> list[str]:
    """Best first, second best last, the rest in between."""
    if len(chunks_best_first) < 3:
        return chunks_best_first
    first, second, *rest = chunks_best_first
    return [first, *rest, second]

def trim_history(turns: list[dict], keep_last: int = 4, summarize=None) -> list[dict]:
    old, recent = turns[:-keep_last], turns[-keep_last:]
    if old and summarize:
        return [{"role": "user", "content": "Summary of earlier conversation: " + summarize(old)}, *recent]
    return recent
See it
What we measured
Measured · position of the answer chunk in a top-5 context
Polder corpus, 34 recursive 512 token chunks, 47 golden questions, hybrid search (BM25 + bge-small, RRF), best first.
Measured 2026-11-04 with corpus/scripts/measure-parts-6-7.mts. Answer accuracy per position needs model calls: not measured yet, needs an API key.
Try it on a real example
Where the answer chunk sat in a top-5 context, 47 questions, hybrid search
The best case for any model.
Choosing
Use it when, avoid it when
- Best-first order and small k
- Summarized history in long chats
- Filling a large context window because it fits
- Assuming a long-context model reads every position equally
What it costs · Ordering is free. Summarizing history costs a small model call every few turns.
In production
Test position effects on your own model: take golden questions, place the answer chunk at positions 1, middle and last among distractors, and compare accuracy. Log context length per question; long-tail questions with huge contexts are where cost and errors pile up. Prompt caching (RAG-04) makes the fixed parts cheap; it does not help the model read the middle.
Watch out
Common mistakes
- Long-context models solved this. They improved; test position on your model.
- More chunks cannot hurt. They add cost and push the answer away from the start.
- History should be kept in full. Old turns crowd out the sources that matter now.
Check yourself
Remember this
Remember these
- Models use the start and end of a long context best.
- Put the best chunk first and keep k small.
- On our corpus the answer was first for 33 of 47 and never below third.
- In chat, summarize history instead of letting it grow.
Say it in an interview
- 01Models use the start and end of long contexts best; Liu et al. showed a U-shaped curve.
- 02I order best first and keep k small, so there is little middle to lose.
- 03On my corpus the answer chunk was first for 33 of 47 questions and never below third.
- 04In chat I summarize old turns and rewrite follow-ups before search.
- 05I would test position effects on my own model before trusting a long context.
Quick quiz