Chapter 7 · concept 5 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Routing, diversity, deduplication and caching
Four ways to shape the candidate list: send questions to the right index, spread results across sources, drop near copies, and reuse answers. Measured: diversity cost us 3 answers, and a semantic cache would confuse two flood questions.
A real question
Three of the top five chunks say the same thing. Is that a waste, and can we reuse answers?
Near copies do waste slots, and spreading results across sources can help a summary. But variety can also push the answer out, and reusing answers needs exact keys. Measure each.
The problem
Why this matters
More variety in the results is always better.
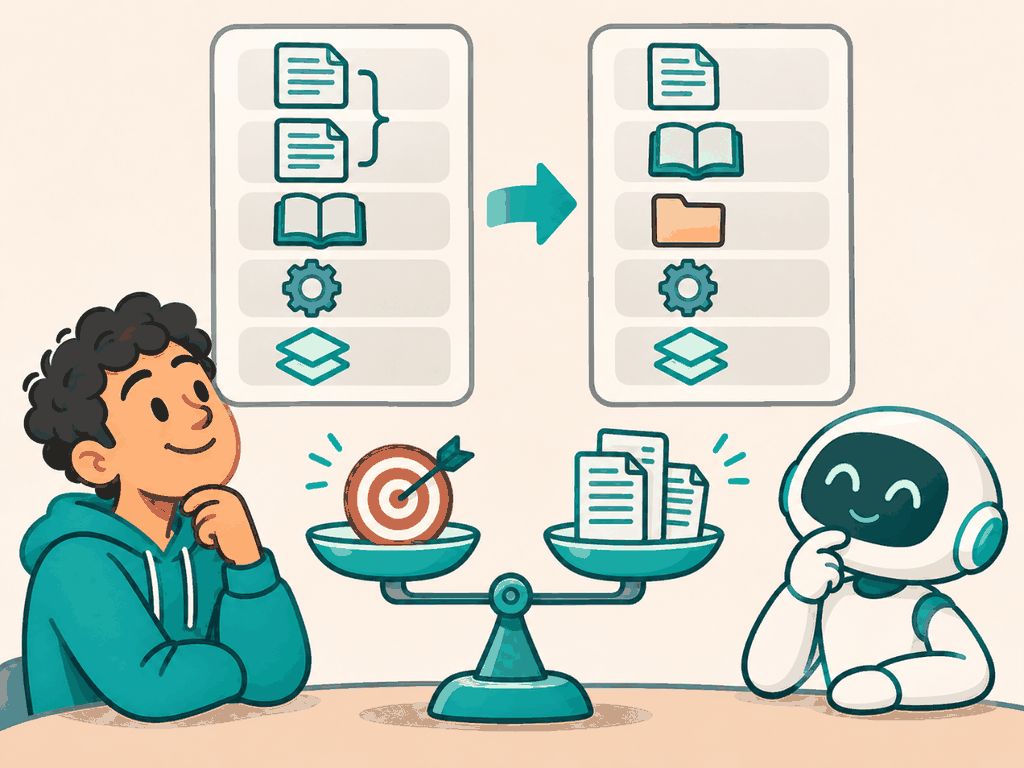
MMR, a common diversity method, raised distinct files in the top 5 from 3.7 to 4.1. It also dropped answers in the top 3 from 44 to 41: for single-fact questions, the best chunk and its neighbour are often both needed.
Why not the simpler way
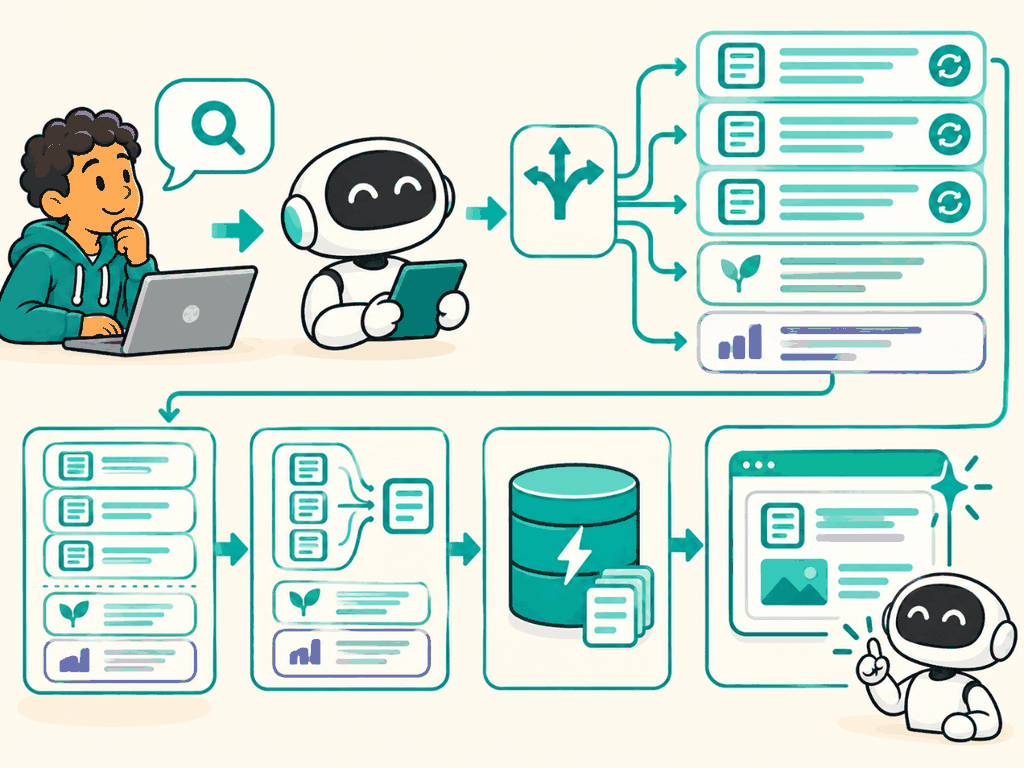
Once retrieval works, the next problems are waste and cost. Versions of the same tariff sheet fill the top 5 with near copies. Popular questions are answered again and again at full price. One big index mixes telecom manuals with bank policies. Each problem has a standard fix, and each fix can quietly hurt quality.
The idea
The idea in plain words
Routing picks which index or tool to search. Diversity re-ranking, such as Maximal Marginal Relevance (MMR, Carbonell and Goldstein, SIGIR 1998), prefers candidates unlike the ones already picked. Deduplication removes near copies. Caching stores answers (or retrieval results) for reuse; a semantic cache reuses them for similar, not identical, questions.
A newspaper editor does not print three versions of the same story, sends sports questions to the sports desk, and reuses yesterday's weather only if it is still yesterday.
How it works
Step by step
 1
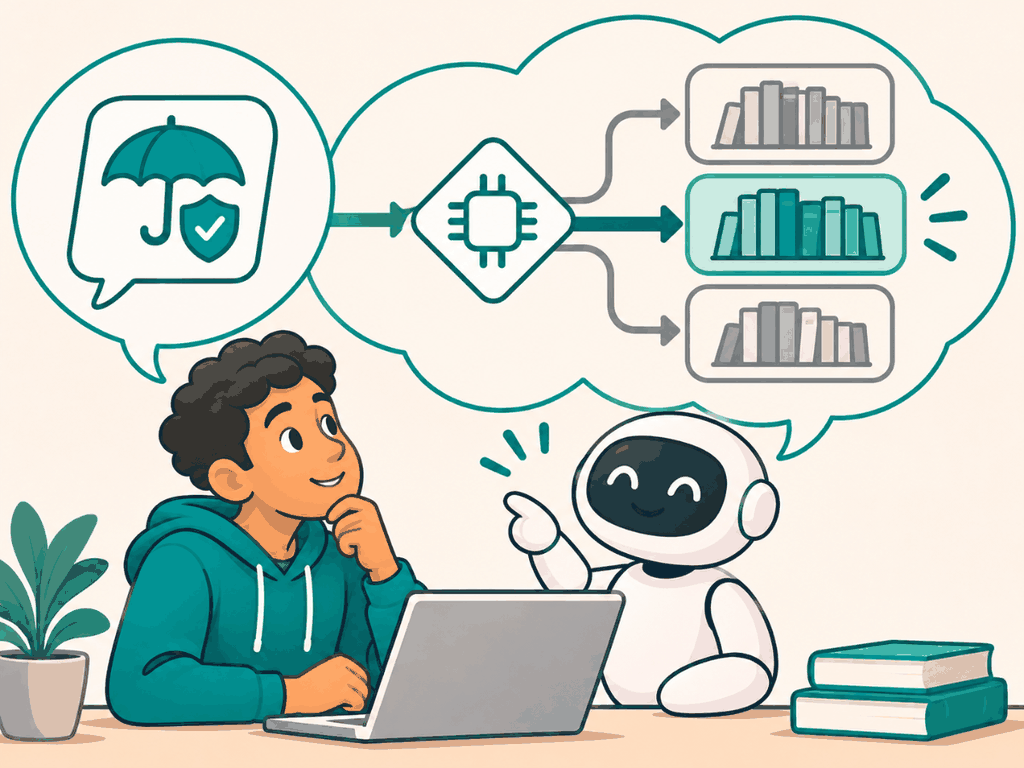
Route to the right index
Send insurance questions to insurance documents. A keyword rule or a small classifier works; a wrong route loses the answer entirely.
 2
Drop near duplicates
Versions and repeated boilerplate create near copies. Keep one per group, or use diversity re-ranking where questions need breadth.
- 3
Cache with exact keys
Reuse an answer only when the question matches and the key facts match: product, postcode, date, version, user role.
In detail
MMR. Pick the best candidate, then repeatedly pick the one with the highest λ · relevance − (1 − λ) · similarity to already picked. We used λ = 0.7 over the top 15.
Dedup. Hash normalized text for exact copies; use vector similarity above a high cut-off (0.95 here) or MinHash for near copies. Prefer the newest valid version (RAG-11).
Routing. Rules on keywords or metadata first; a classifier or a model call when rules are not enough. Always allow a fallback to search everything.
Caching. Exact-match caches are safe. Semantic caches need a strict similarity cut-off plus exact matching on codes, numbers and dates, and must be invalidated when the source documents change.
The code
Try it in Python
import hashlib, re

def cache_key(question: str, user_role: str, corpus_version: str) -> str:
    exact = sorted(re.findall(r"[A-Z]{1,4}-?\d[\w.-]*|\b\d{4}\b|\d+(?:[.,]\d+)?", question))
    norm = " ".join(question.lower().split())
    return hashlib.sha256(f"{norm}|{exact}|{user_role}|{corpus_version}".encode()).hexdigest()

# Exact-match cache: safe. A semantic cache must still compare the `exact` list,
# and corpus_version changes whenever a document is updated, which expires old entries.
See it
What we measured
Measured · diversity, duplicates and cache risk
Polder corpus, 34 recursive 512 token chunks, 47 golden questions, bge-small vector search. MMR with λ 0.7 over the top 15.
Measured 2026-11-04 with corpus/scripts/measure-parts-4-7.mts. Routing and a live cache were not measured; our corpus is one small index.
Try it on a real example
Two golden questions a semantic cache would treat as one
Similarity 0.893
Is flood damage covered in postcode 1011 in May 2026?
The most similar pair in our golden set with different answers.
Choosing
Use it when, avoid it when
- Dedup of near copies and old versions
- Exact-key caching with expiry on document change
- MMR for broad questions such as summaries
- MMR on single-fact questions without measuring
- Semantic caching on similarity alone
What it costs · Dedup and MMR: cheap vector math. Caching saves model calls but needs invalidation. Routing may add a classifier call.
In production
Measure cache hit rate and, more importantly, wrong-hit rate: sample cached answers and check them against a fresh run. Invalidate cache entries by document id when a document is updated or deleted (RAG-12). For routing, log the chosen route and how often the fallback fires; a route that is often wrong hides answers completely, which no reranker can fix.
Watch out
Common mistakes
- Diversity always improves results. It cost 3 answers in our top 3.
- Similar questions have the same answer. Our most similar differing pair scored 0.893.
- A cache is free speed. A wrong hit is a wrong answer delivered quickly.
Check yourself
Remember this
Remember these
- Route only when indexes are clearly separate, and log the route.
- Near-duplicate chunks waste slots: we found 6 pairs above 0.95 similarity.
- Diversity helps broad questions and hurt our single-fact ones: 44 to 41.
- Cache on exact keys, and expire entries when documents change.
Say it in an interview
- 01I dedup near copies and keep the newest valid version.
- 02MMR raised source variety from 3.7 to 4.1 files but cost 3 answers in the top 3 on my corpus.
- 03Two flood questions scored 0.893 alike with different answers, so my cache keys on postcode and date.
- 04Caches expire when the source documents change.
- 05Routing gets a fallback to full search, and I log every route.
Quick quiz