Chapter 10 · concept 2 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Building a golden dataset
How we built 52 test questions for this course: real needs, an exact evidence sentence for each, deliberate hard cases, and a script that checks every quote is really in the corpus.
A real question
Where do good test questions come from?
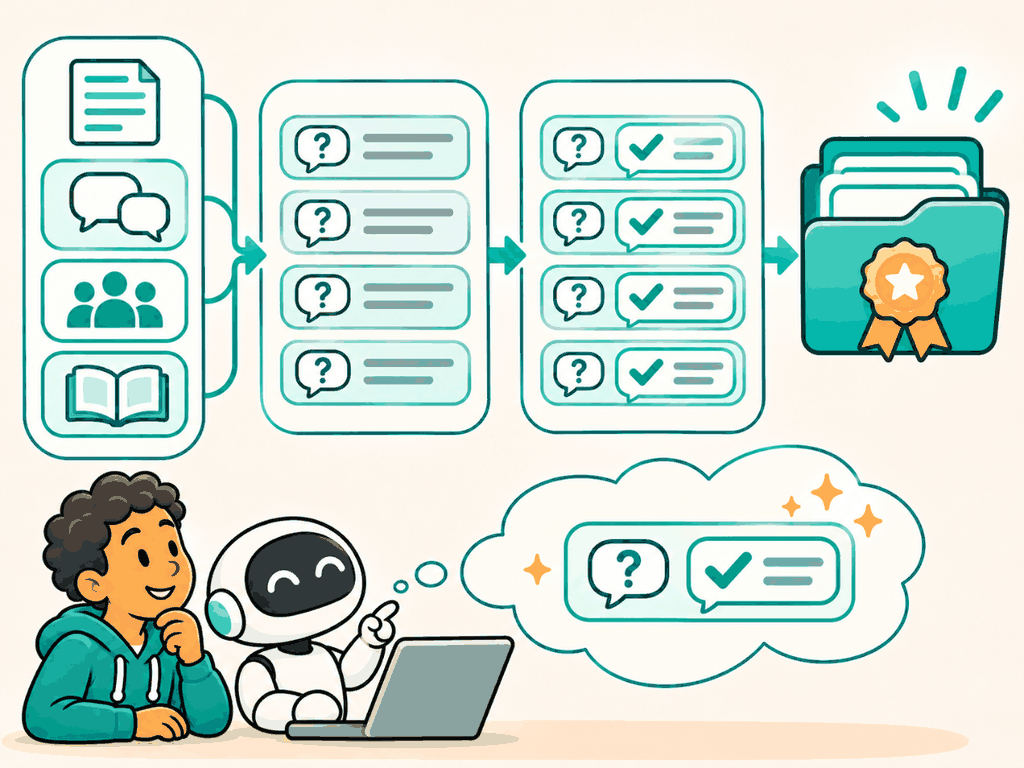
From the questions your users really need answered, written down with the exact sentence that answers them. Add the hard cases on purpose, check every quote with a script, and keep the set small enough to review by hand.
The problem
Why this matters
Have a model generate a thousand test questions from the documents.
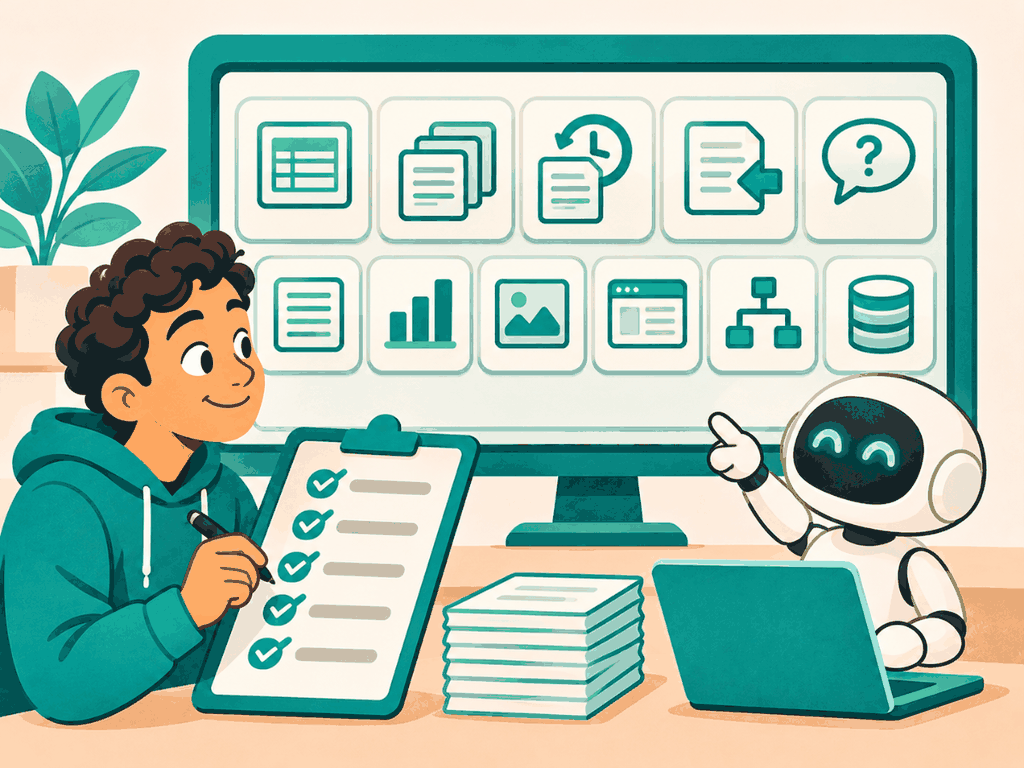
Our set has 52 questions, each with an evidence sentence checked against the corpus. It covers 11 kinds of case, from tables and old versions to injected instructions and questions with no answer. Generated questions can help, but only after a person checks them.
Why not the simpler way
Every number in this course comes from 47 answerable questions out of a set of 52. If those questions were sloppy, every comparison would be too. A golden set is the foundation of evaluation, and the place where shortcuts cost the most later.
The idea
The idea in plain words
A golden dataset is a versioned list of test cases. Each case has a question, the expected answer, the expected documents and the evidence that proves it, plus metadata such as case type and user role. It is small, varied and checked.
An exam with an answer key, where every answer points to the page in the textbook.
How it works
Step by step
 1
Start from real needs
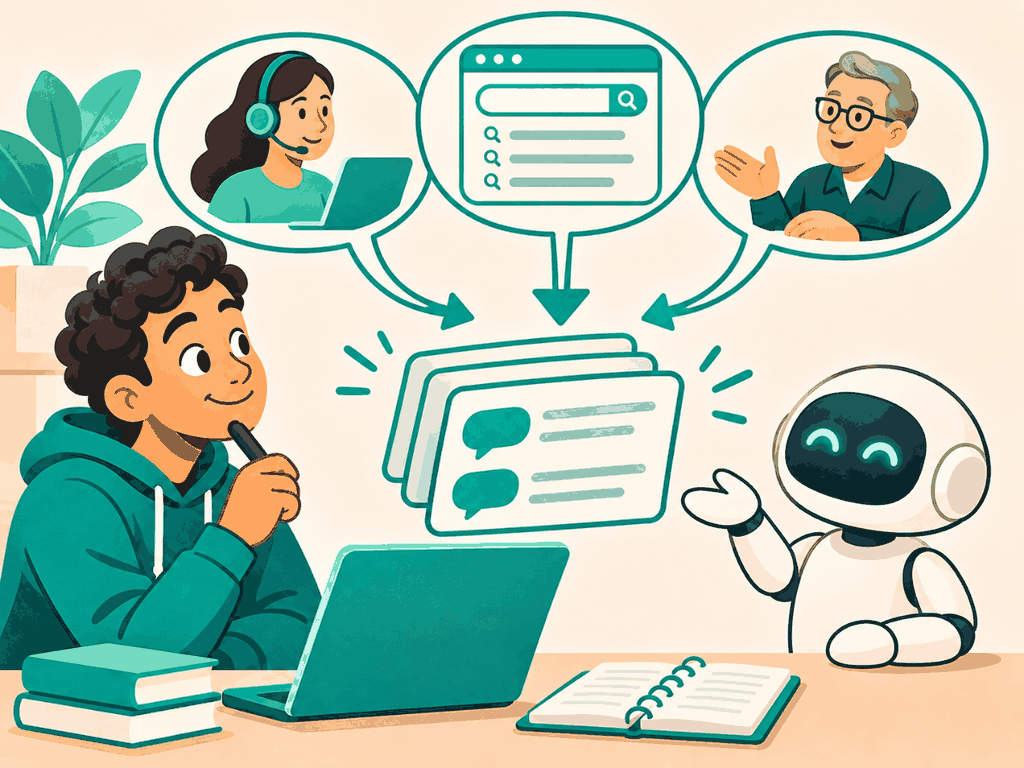
Support tickets, search logs, expert interviews. Write the question the way a user would ask it.
- 2
Copy the exact evidence
For each question, the expected answer, the document id and the exact sentence that proves it.
 3
Verify, then freeze
A script confirms each evidence sentence is in the corpus. A person reviews the answers. Then the set is versioned and only changed on purpose.
In detail
Fields. id, question, case_type, expected_doc_ids, answer, evidence, expected_abstain, and optional user_role or conflict_with.
Case types in ours. answerable 17, table 8, version 8, exact-code 4, multi-clause 3, restricted 3, paraphrase 2, conflict 2, abstain 2, injection 2, multi-doc 1.
Checks. Our check_golden.py loads every document and confirms each evidence string appears verbatim. It also lists documents no question uses: 5 of our 25, a hint of gaps.
Bias. We wrote questions while reading the documents, so they reuse the documents' words. That favours keyword search (RAG-27). Real traffic and paraphrased questions balance it.
Generated questions. A model can draft questions per chunk. Treat drafts as candidates: check the evidence, rewrite in user language, drop trivial ones.
The code
Try it in Python
import json, pathlib

def check(golden_path: str, corpus_dir: str):
    docs = {p.stem: p.read_text() for p in pathlib.Path(corpus_dir).glob("*.md")}
    problems = []
    for line in open(golden_path):
        g = json.loads(line)
        if g.get("expected_abstain"):
            continue
        texts = [t for name, t in docs.items() if any(name.startswith(d) for d in g["expected_doc_ids"])]
        if not any(g["evidence"] in t for t in texts):
            problems.append(g["id"])
    return problems     # must be empty before the set is frozen
See it
What we measured
Measured · our golden set
corpus/golden/golden_v1.jsonl over 25 English Polder documents, checked with corpus/scripts/check_golden.py.
Checked 2026-11-04 with npm run check-golden.
Try it on a real example
Two items from our golden set
g-01 · exact-code
Answer: Mesh pairing failed because the mesh extender runs old firmware…
Evidence: | E4012 | Mesh pairing failed | Mesh extender on old firmware |
Document: SYN-TEL-FIBERBOX
A retrieved chunk counts as a hit only if it contains the evidence line exactly.
Choosing
Use it when, avoid it when
- Hand-checked questions with exact evidence
- Deliberate hard cases and unanswerable questions
- A script that verifies every quote
- Thousands of unchecked generated questions
- Questions only in the documents' own words
What it costs · A day or two for 50 questions. Grows cheaply from real bug reports.
In production
Grow the set from production: when a user reports a wrong answer, add that question with the right evidence. Keep slices balanced so one type does not dominate the total. Version the set, and when you change it, re-run the baseline so old and new numbers stay comparable.
Watch out
Common mistakes
- More questions are always better. 50 checked questions beat 1,000 unchecked ones.
- Only answerable questions matter. Abstain, injection and role cases catch the worst failures.
- The set is done once written. It grows with every real failure.
Check yourself
Remember this
Remember these
- Write questions from real needs, in users' words.
- Store answer, document id and the exact evidence sentence.
- Cover hard cases on purpose: tables, versions, codes, conflicts, no answer, injection, roles.
- Check every quote with a script and review by hand before freezing.
Say it in an interview
- 01My golden set has 52 questions, each with the exact evidence sentence and document id.
- 02It covers 11 case types, including tables, versions, conflicts, injection and roles.
- 03A script checks every evidence string is in the corpus before the set is frozen.
- 04I know its bias: questions reuse document wording, so I add paraphrases.
- 05Real user failures become new golden questions.
Quick quiz