10
Measuring
Know with numbers whether a change made things better.
Concept 10.1
Why measure, and what to measure
Without a fixed test, every change is a guess. What to measure at each stage of a RAG system, and three changes from this course where the obvious number told the wrong story.
Concept 10.2
Building a golden dataset
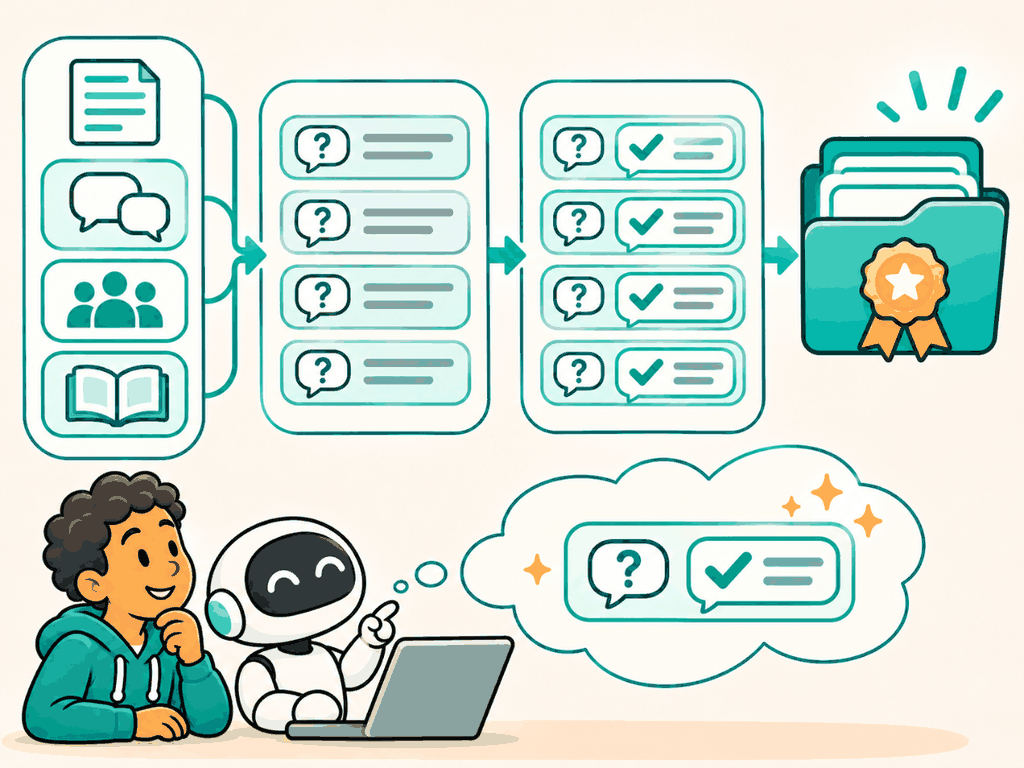
How we built 52 test questions for this course: real needs, an exact evidence sentence for each, deliberate hard cases, and a script that checks every quote is really in the corpus.
Concept 10.3
Retrieval metrics: precision, recall, MRR, nDCG
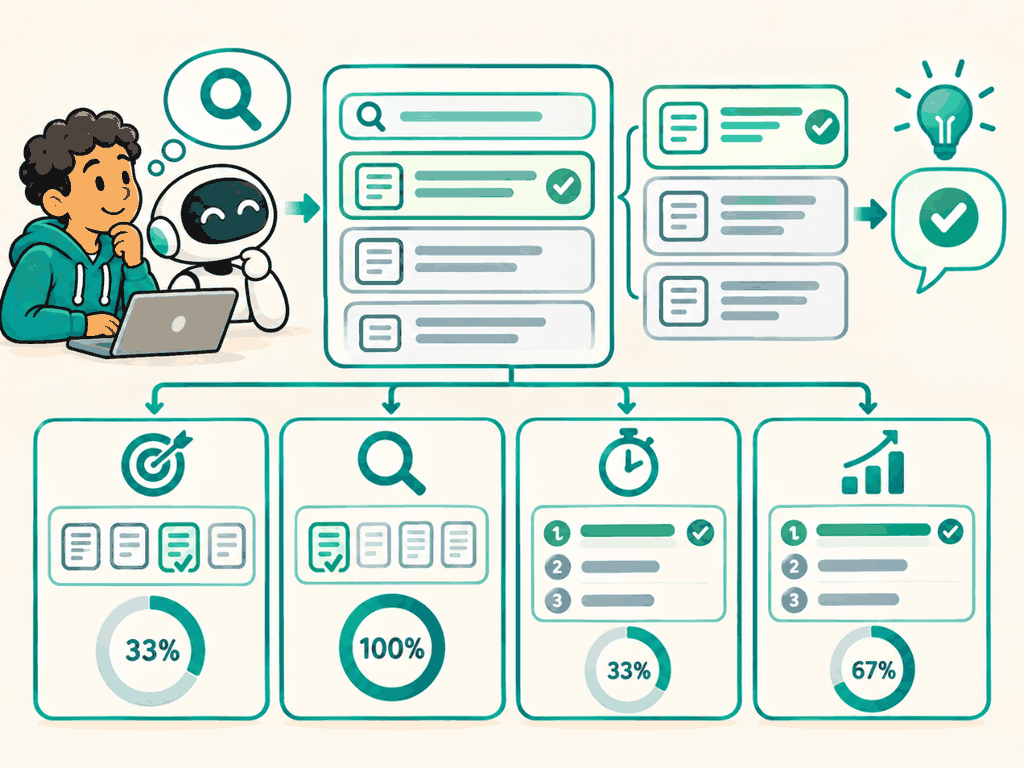
Four numbers for “did search find it”, what each one counts, and all four computed for vector, BM25 and hybrid search on our 47 questions, including why precision@3 can never pass 0.33 here.
Concept 10.4
Faithfulness and answer correctness
Two different questions about an answer: is it true (correctness), and does it come from the sources (faithfulness)? How to measure each, from cheap string checks to claim-by-claim judging.
Concept 10.5
LLM as judge, and judging the judge
Using a model to grade answers scales evaluation, and adds a new thing to test. How to write narrow rubrics, which biases to expect, and how to check a judge against human labels before trusting it.
Concept 10.6
Offline and online evals, regression tests and slices
Run the golden set in CI and block changes that lose answers; split results by case type so a weak slice cannot hide in the average; and watch live traffic for what the golden set misses.
Chapter 10 recap