Chapter 10 · concept 3 of 6 · show all
2Tokens, cost and your first RAG
4Chunking
- 4.1Why we chunk, and the main chunking strategies
- 4.2Structure aware chunking and tables
- 4.3Chunk size, overlap and token based sizing
- 4.4Contextual chunking and late chunking
- 4.5Parent child and multi representation indexing
- 4.6Chunk metadata, provenance and the chunking debugging playbook
- Chapter overview
7Finding the right chunks
8When retrieval fails
Retrieval metrics: precision, recall, MRR, nDCG
Four numbers for “did search find it”, what each one counts, and all four computed for vector, BM25 and hybrid search on our 47 questions, including why precision@3 can never pass 0.33 here.
A real question
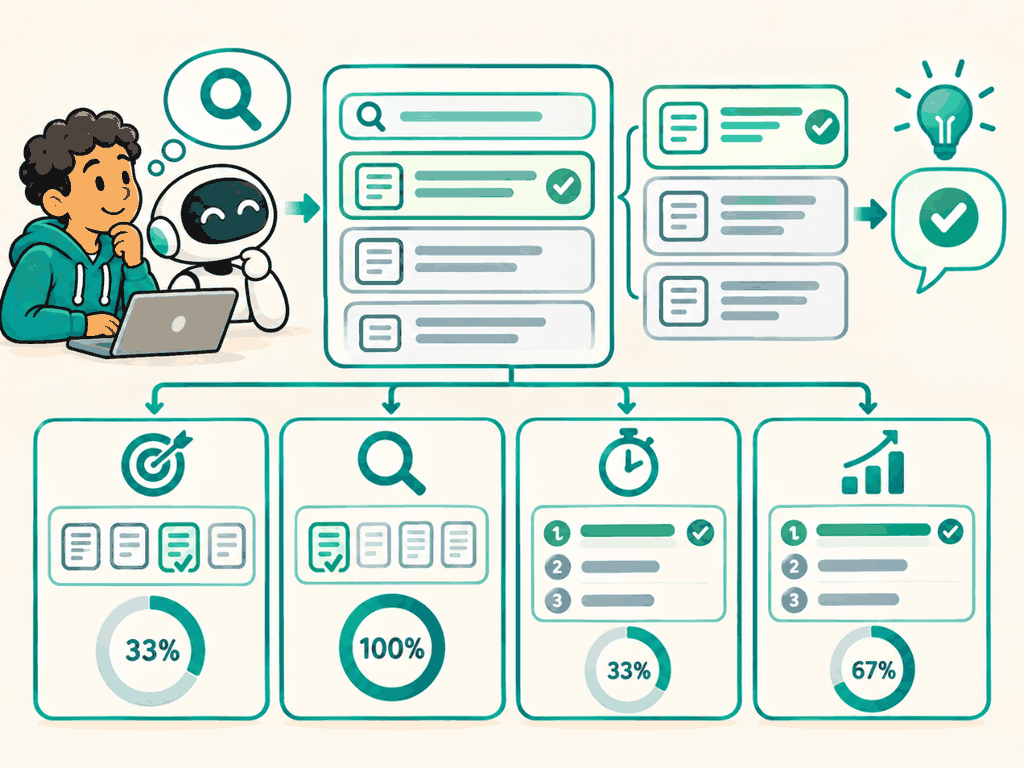
Search returned 3 chunks and one holds the answer. Is that 33% or 100%?
Both, depending on the question you ask. Precision asks how much of what was shown is relevant; recall asks whether the relevant thing was found. MRR and nDCG ask how high it was. Each number answers one question.
The problem
Why this matters
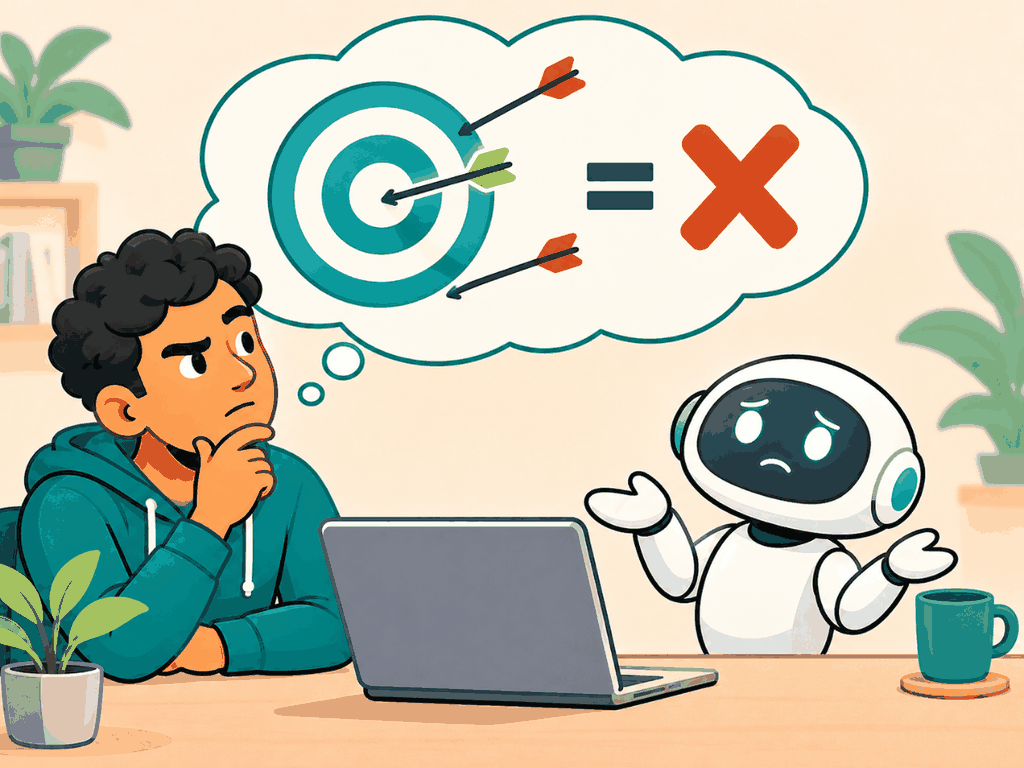
Precision@3 is 0.34, so search is mostly wrong.
46 of our 47 questions have exactly one chunk holding the evidence. Three results can then hold at most one hit, so precision@3 tops out near 0.33. BM25's 0.34 is close to perfect.
Why not the simpler way
Retrieval metrics come from web search, where many pages can be relevant. In RAG, usually one or two chunks hold the answer. Reading the classic numbers without that context leads to wrong conclusions, such as thinking a precision of 0.34 is poor.
The idea
The idea in plain words
For one question with a ranked list and a set of relevant items:
- Recall@k = relevant items in the top k / all relevant items. Averaged over questions, it is our "evidence recall@3".
- Precision@k = relevant items in the top k / k.
- Reciprocal rank = 1 / rank of the first relevant item; MRR is its mean.
- nDCG@k = DCG / ideal DCG, where DCG sums gain / log2(rank + 1).
A treasure hunt: recall asks whether you found the treasure, MRR how quickly, precision how many empty boxes you opened on the way.
How it works
Step by step
 1
Recall@k: found at all?
The share of relevant chunks found in the top k. With one relevant chunk per question, as here, that is the share of questions whose evidence is in the top k (also called hit rate). The main number for RAG: the model cannot use what it never sees.
 2
MRR: how high?
1 divided by the rank of the first relevant chunk, averaged. Rank 1 scores 1, rank 2 scores 0.5, rank 4 scores 0.25.
 3
nDCG: graded and position-weighted
Adds up relevant hits with a discount for lower ranks, divided by the best possible. Handles several relevant chunks and grades of relevance.
In detail
Relevance labels. We mark a chunk relevant if it contains the golden evidence string; this is automatic and strict. Graded labels (2 = answers fully, 1 = partly) need human or model judgement.
Which k. Use the k you actually pass to the model (RAG-29). Recall@10 only matters if a reranker reads the top 10.
Averages hide. Report per slice (RAG-44) and keep per-question ranks for diffs (RAG-39).
Our code. src/lib/rag/metrics.ts implements recallAtK, precisionAtK, reciprocalRank, mrr and ndcgAtK, and is unit tested.
The code
Try it in Python
import math

def recall_at_k(ranked, relevant, k):    return len(set(ranked[:k]) & set(relevant)) / len(relevant)
def precision_at_k(ranked, relevant, k): return len(set(ranked[:k]) & set(relevant)) / k
def reciprocal_rank(ranked, relevant):
    return next((1 / (i + 1) for i, x in enumerate(ranked) if x in relevant), 0.0)

def ndcg_at_k(ranked, gains: dict[str, float], k):
    dcg = sum(gains.get(x, 0) / math.log2(i + 2) for i, x in enumerate(ranked[:k]))
    ideal = sum(g / math.log2(i + 2) for i, g in enumerate(sorted(gains.values(), reverse=True)[:k]))
    return dcg / ideal if ideal else 0.0
See it
What we measured
Measured · retrieval metrics on 47 golden questions
Polder corpus, 34 recursive 512 token chunks. Relevant = chunk contains the evidence string (46 questions have one relevant chunk, 1 has more). Vector: bge-small. Hybrid: RRF of the top 10 from each.
Measured 2026-11-04 with corpus/scripts/measure-parts-4-7.mts, using src/lib/rag/metrics.ts.
Try it on a real example
All four metrics, three retrievers, 47 questions
bge-small
Finds most answers, often not first.
Choosing
Use it when, avoid it when
- Recall@k at your real k as the main retrieval number
- MRR or nDCG to see ranking gains
- Per-slice reports
- Judging precision without its ceiling
- Comparing metrics across different golden sets or relevance rules
What it costs · Free once the golden set has evidence strings: a few lines of code per metric.
In production
Put recall@k and MRR on the dashboard for every index build and retrieval change. Add nDCG once you have graded labels. Never compare numbers across different golden sets or relevance rules; a stricter rule lowers every metric without anything getting worse.
Watch out
Common mistakes
- Low precision means bad search. With one relevant chunk, 0.33 at k = 3 is the maximum.
- Recall@10 is what matters. Only the chunks that reach the model matter.
- One metric is enough. Reranking showed up in MRR and rank 1, not in recall@3.
Check yourself
Remember this
Remember these
- Recall@k: is the evidence in the top k? The first number for RAG.
- Precision@k: share of the top k that is relevant; mind the ceiling.
- MRR: how high the first relevant chunk is.
- nDCG: position-weighted, handles several relevant chunks and grades.
Say it in an interview
- 01Recall@k is my main retrieval number, at the k I really pass to the model.
- 02On my corpus BM25 and hybrid reached recall@3 of 1.000; vector 0.936.
- 03Precision@3 of 0.34 is near its ceiling, because most questions have one relevant chunk.
- 04I use MRR and nDCG to see ranking gains that recall cannot show.
- 05Relevance is automatic: a chunk is relevant if it contains the golden evidence string.
Quick quiz